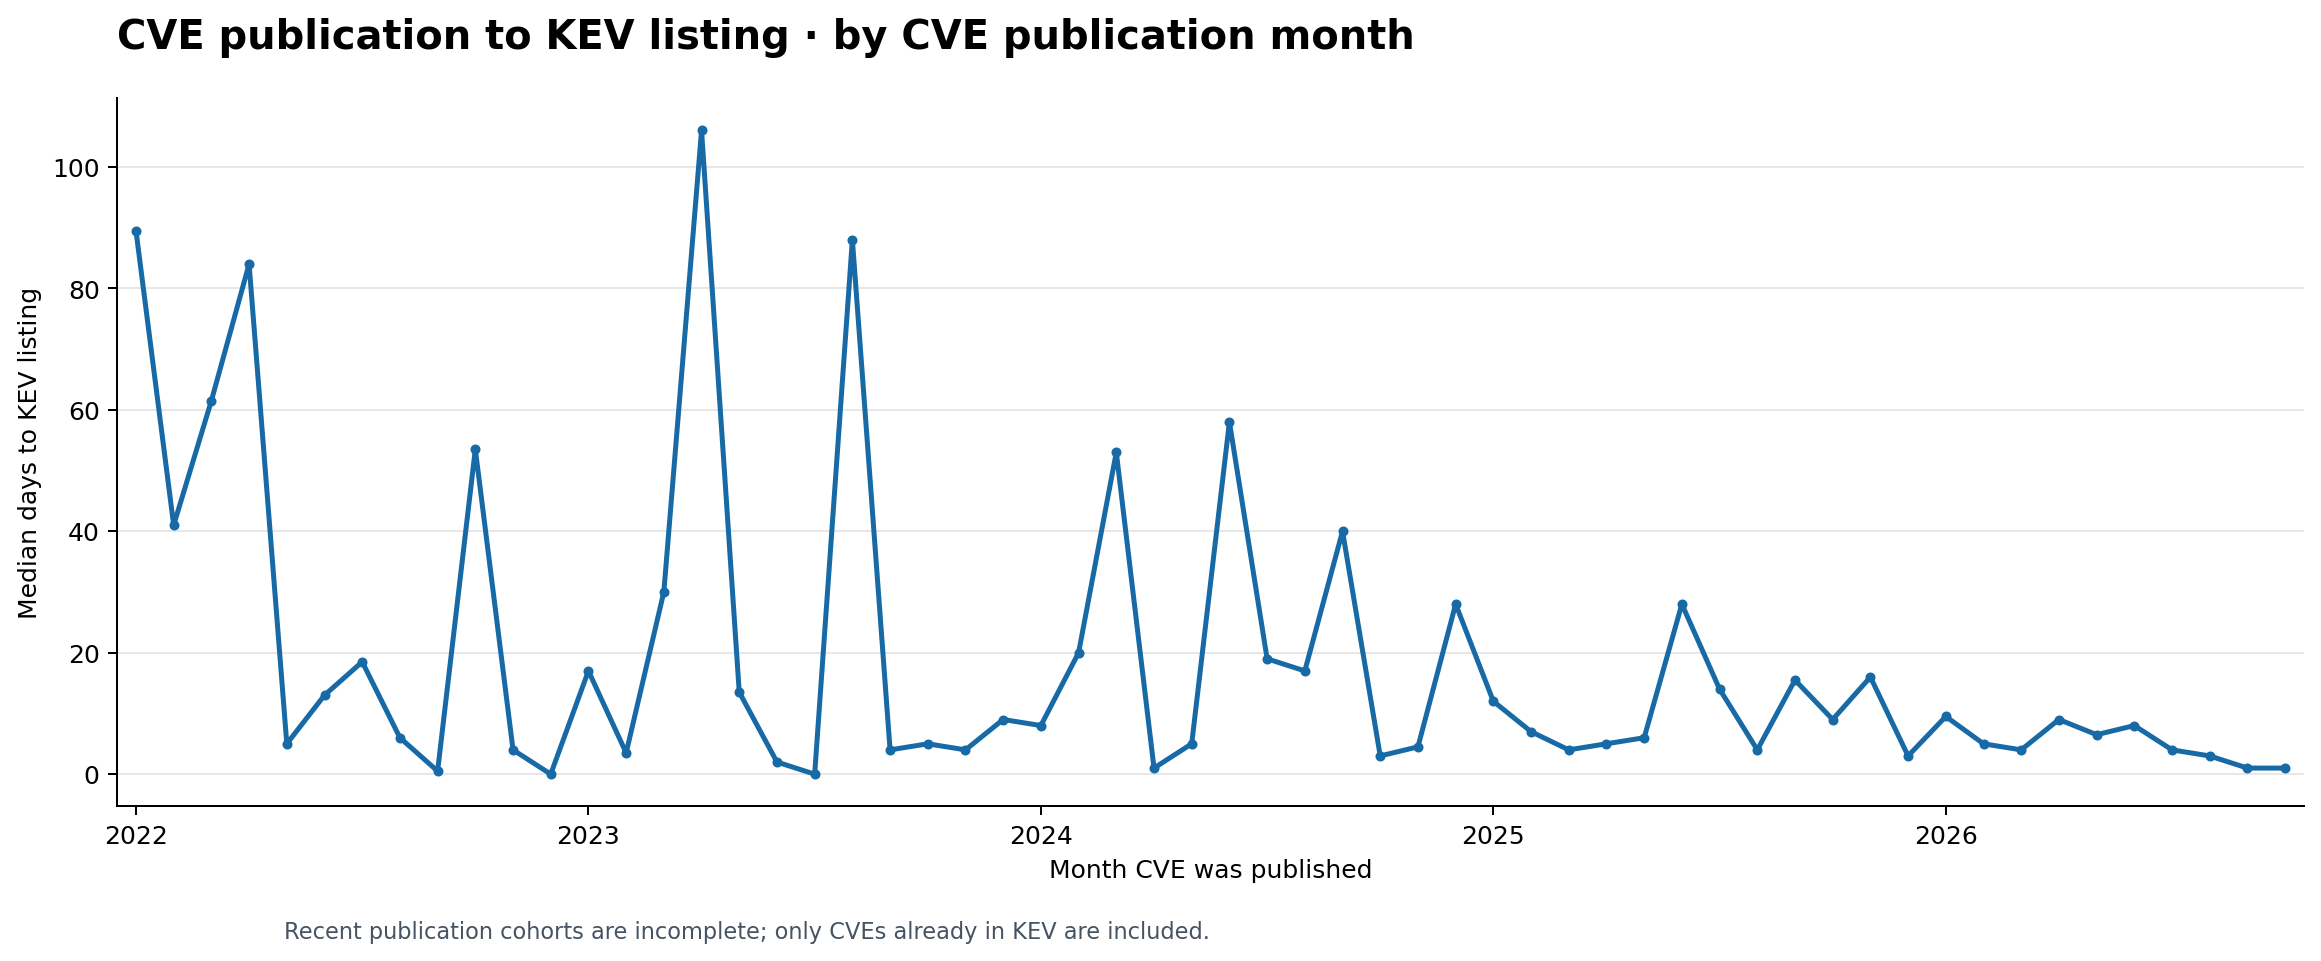
In my previous article about CVEs, we looked at CVE growth. But we didn’t look at the time between detecting a vulnerability and identifying an exploit. The concern is that AI is accelerating not only the number of CVEs and patches, but also exploit creation, shortening the time between a CVE being reported and an exploit becoming available.
The overall trend shouldn’t come as a surprise. Although the spikiness of the data wasn’t so expected. There are a couple of possible explanations for this:
New exploits occurring that have then been attributed to older CVEs. In some respects, the shrinking fluctuation range says a lot as well; after all, as we find more vulnerabilities, the chances of exploits being linked to a more recent issue increase. Furthermore, if you’re using CVEs to find possible exploits to leverage, a more recent one is better, as targets are more likely to be unpatched.
The volume of data points is lower, so the median is more easily influenced by outliers.
To be transparent, we sourced the underlying data for this graph from a public GitHub repo that curates data from a range of trustworthy sources, from the FBI to CVE.org (more details here). The data also supports vulnerabilitydata.io, which asks big questions like how AI is impacting society.
The plot uses a published monthly dataset that joins CISA’s dateAdded to the official CVE record’s datePublished, groups records by KEV addition month, and excludes CVEs published before KEV launched. Its October 2026 value is partial, based on data fetched on 26 October 2026.
Other data sources
While we’re looking for data, the following sources came up as potentially interesting.
CVE publication → its earliest recorded exploitation evidence or KEV addition
Annual analyses and record-level data; no verified public monthly aggregate here.
Medium, conditional on access and the evidence behind each record. Its published example calculates intervals from NVD publication to VulnCheck KEV addition. Vulnerability Research
CVE publication → first dated public exploit or PoC evidence
No verified comprehensive monthly aggregate; join and deduplicate individual records.
Medium to low. A listing or sighting can lag the code’s first publication, and a public PoC does not establish exploitation in the wild. CIRCL explicitly distinguishes these event types. exploit-db.com
Daily changes in predicted exploitation probability
Daily historical scores, but not a date of exploitation or PoC publication.
High for what the score said on a given day; unsuitable as the endpoint for the requested delay. Model changes also affect comparisons across years. first.org
Conclusion
Regardless of the vulnerability, and an organizations approach to being secure, be that:
Patching as fast as possible.
Establish a robust security architecture that provides strong (compensating) controls. In other words, remove or reduce the ability for someone to exploit a vulnerability to a level where the patch cost-benefit formula doesn’t pay.
We need to evaluate the likelihood of exposure as soon as the CVEs are published.
In our first post on Moving Open-Source Observability closer to turn-key solutions, we discussed how we can automate the source-to-pipeline. But turn-key solutions also flow data to the backend and provide logs and metrics that are contextually aware of the systems being monitored.
While detecting sources and building the capture mechanism may seem more challenging at first glance, it is easier – we have a defined technology, and our observability agent defines the output structure. So what makes the pipeline to the backend more complex?
We’re more likely to have a variety of products, and some products may have functional overlaps.
Greater configuration diversity in how tools can be configured.
Greater contextual awareness is needed.
Let’s break these down in more detail.
Greater variety of tools means we need a common way to set up transformations; otherwise, the mechanics of a transformation process in our pipeline will explode in complexity.
One benefit of going open source is that you can choose the tools that fit your needs for log analytics, metrics, alert routing, and so on, but this can lead to functional overlaps. For example, you may use Prometheus for infrastructure-based metrics, but want to use Elastic APM for Application Performance Management (APM) as you’re using an Elastic Java stack for app development.
The different approaches to configuring tools, or configuration diversity, is probably the single largest challenge, and the number of approaches multiplies the number of configuration permutations that must be achievable. While there appears to be some initia behind the support the Prometheus mixin framework which provides templates for different scenarios such as infrastructure dashboards and alerts. It is far from universal adoption today. For example, Prometheus and Grafana support its use. But other solution stacks such as Elastic do not. If you align on a common technology stack, the chances of a harmonised configuration process rise.
We need contextual awareness from the source, as well as the collected data, to map data to the table(s). For efficiency, if we can avoid putting all metrics into a single table, queries could have one less dimension to filter. Context awareness will inform how we render the dashboards and set alert thresholds. For example, general filesystem storage capacity thresholds would be hugely different to database storage thresholds.
All of this means that if we want a deterministic, transformation-based process, we’ll end up with an unsustainable set of combinations that need to be mappable, testable, and maintainable as the different solutions grow, evolve, and occasionally get archived as contributions dry up.
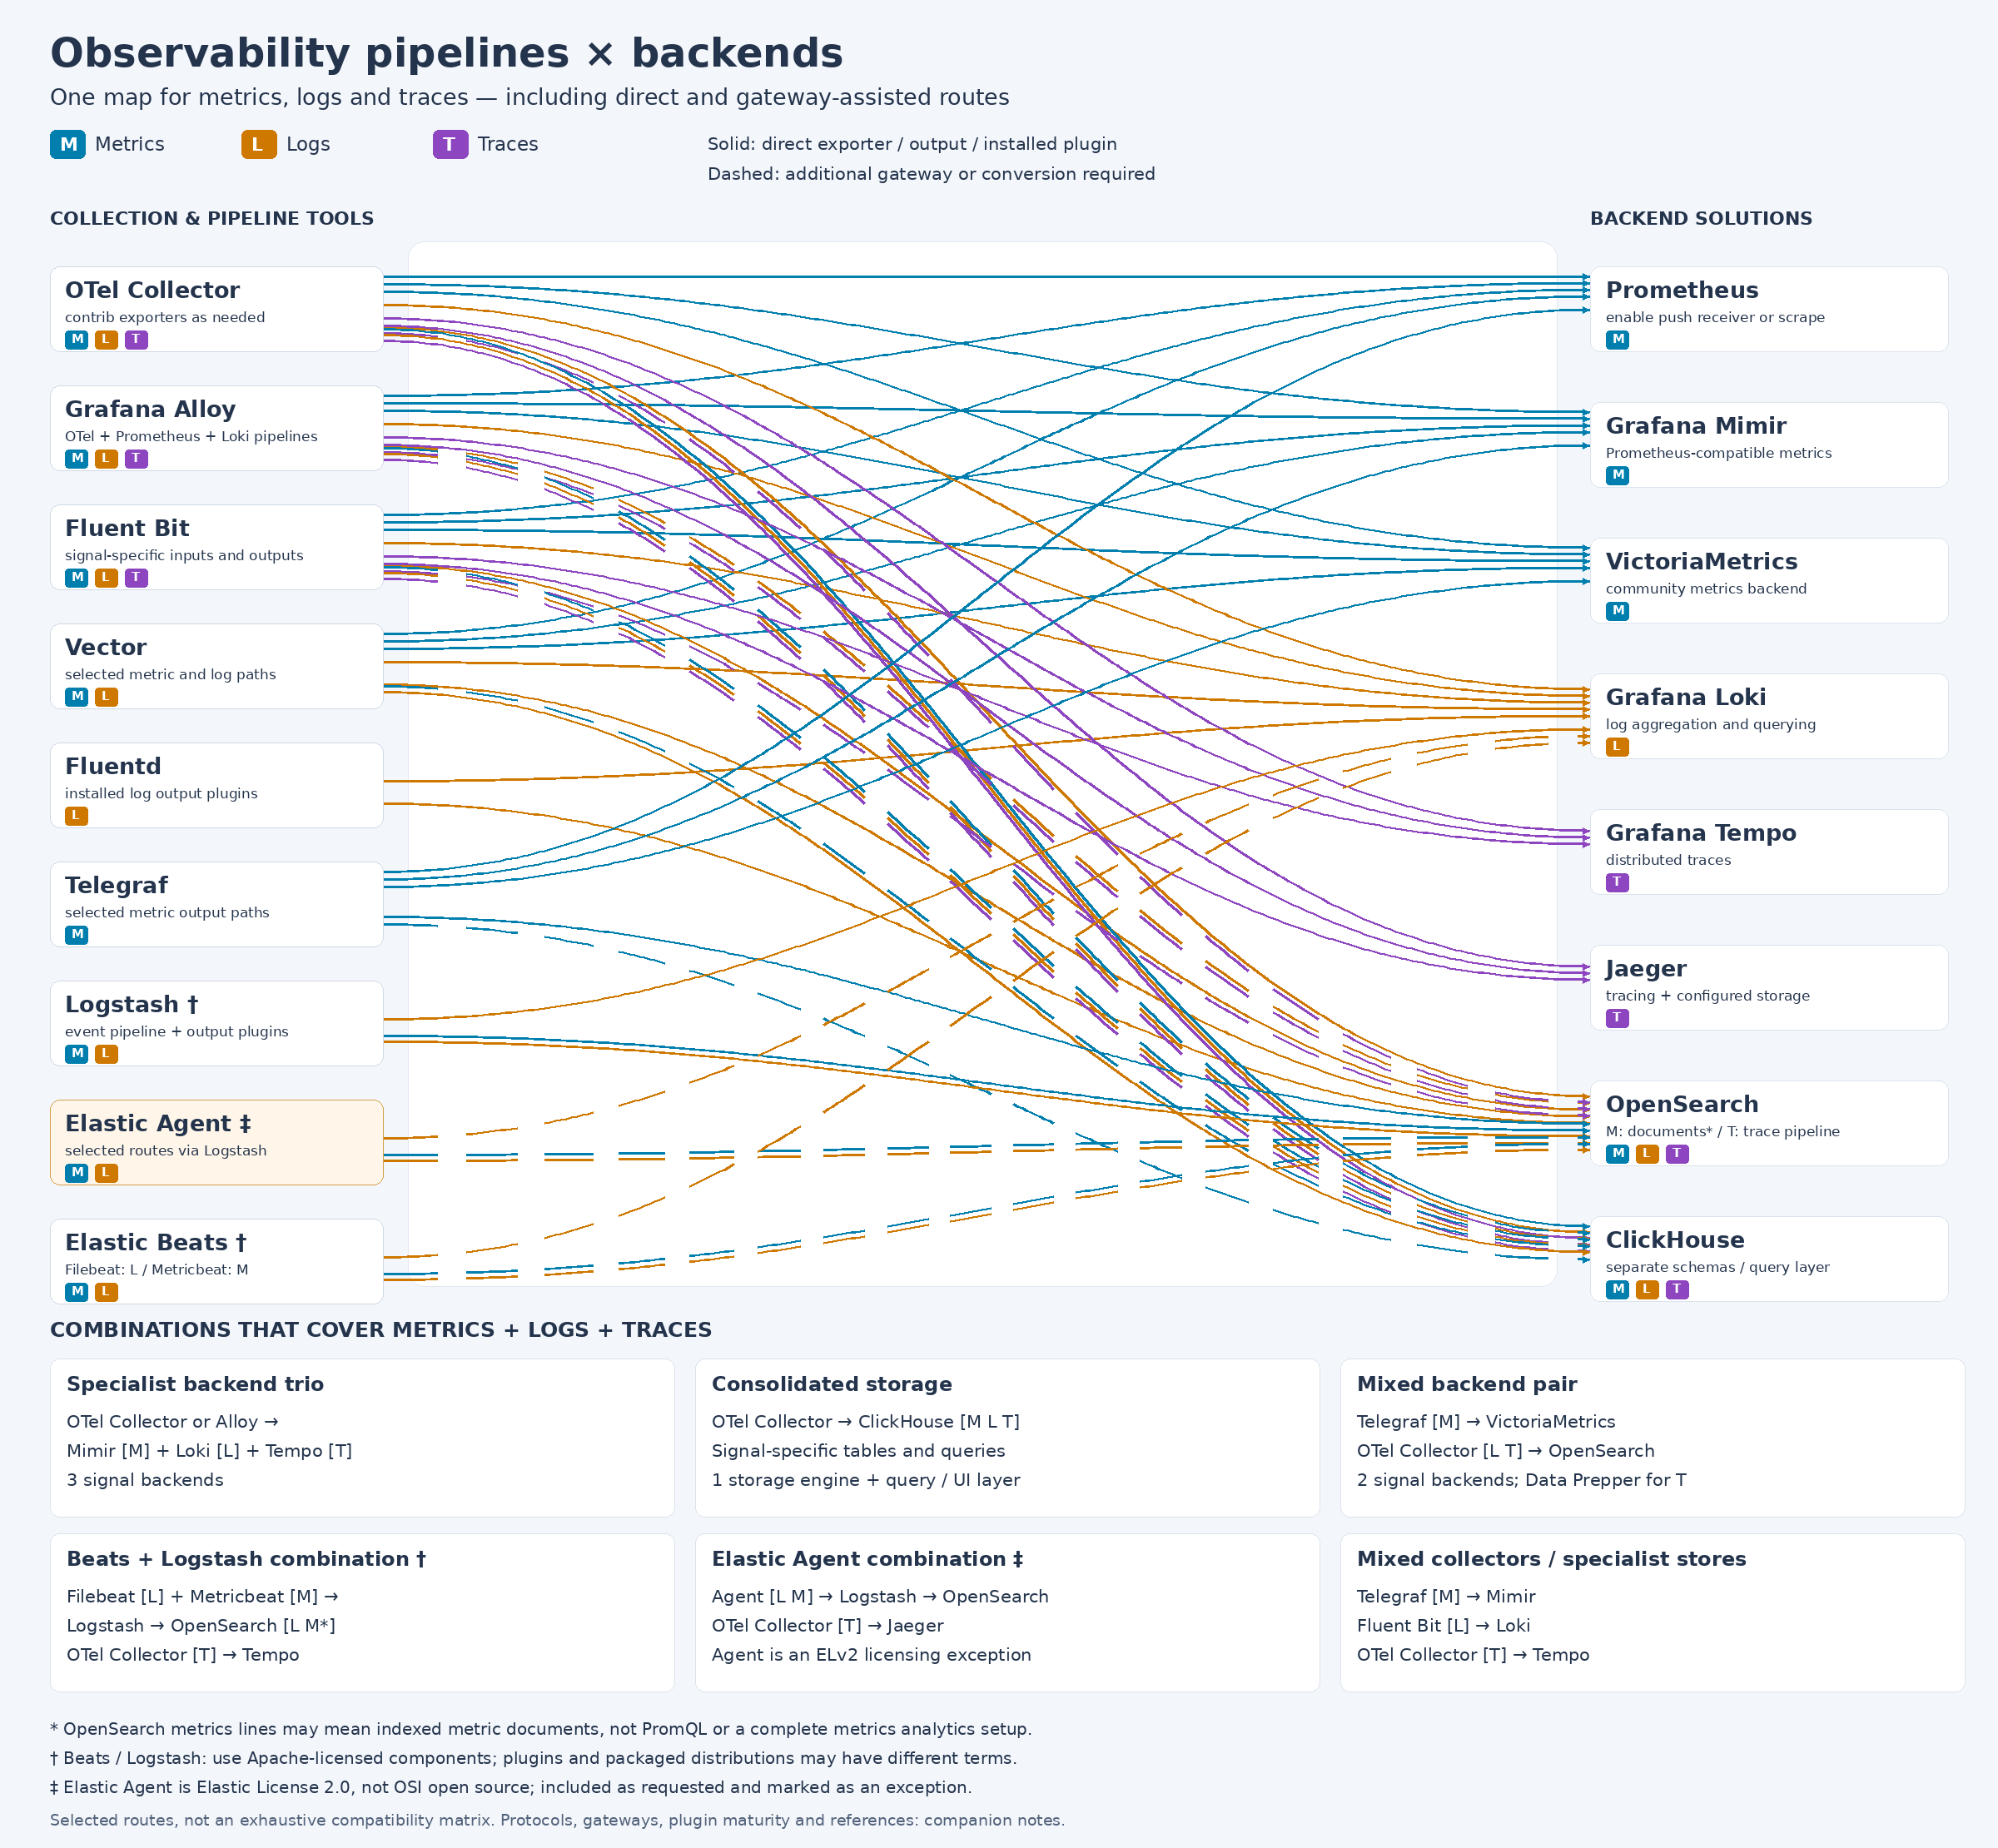
As turnkey solutions, bring an opinionated answer and either build their own backends from scratch (e.g. Oracle’s Enterprise Manager) and leveraging open source as building blocks – they effectively eliminate the challenges of functional overlaps and configuration diversity – at the same time removing that flexibility. To underline how messy things could get, we experimented in a branch of the repo to see how messy it could get, while trying to keep the divergence as narrow as possible. This diagram illustrates the point visually.
Solution
If a deterministic approach is unsustainable, are there options to ease the challenge or achieve a solution?
Simplification option
One option that can simplify, but certainly doesn’t solve, the challenge is to leverage OpenTelemetry’s work on semantic conventions, where they have been cultivating naming conventions that define data elements likely to be transmitted. When you manually map data, the process becomes more intuitive (and therefore quicker) and improves the chances of an AI agent mapping successfully. In some respects, this is like middleware-driven efforts to build data ontologies, so you need to avoid the problems global ontologies had.
Bringing AI to the game
Because configuration is linguistic and well documented, you can apply an LLM-based approach to the problem. The process of mapping from the ingestion part of the pipeline to the back end needs to be flow-driven so we can:
Perform a validation process by selecting and using validation tools to verify the configuration(s).
When validations fail, the process can be pushed back to the configuration stage again.
When users are in the loop, it becomes possible to drive a conversation for more clarity.
With a conversational process, it becomes possible to create in-pipeline transforms as a result of user conversation, along with simpler transforms to handle possible data formats and names.
What we’re describing here isn’t trivial, and could arguably be offered as a commercial product in its own right. The config management feature of our OpAMP solution also provides meaningful inputs, as it defines valid data types for observability agents like Fluent Bit where a concrete schema is not provided.
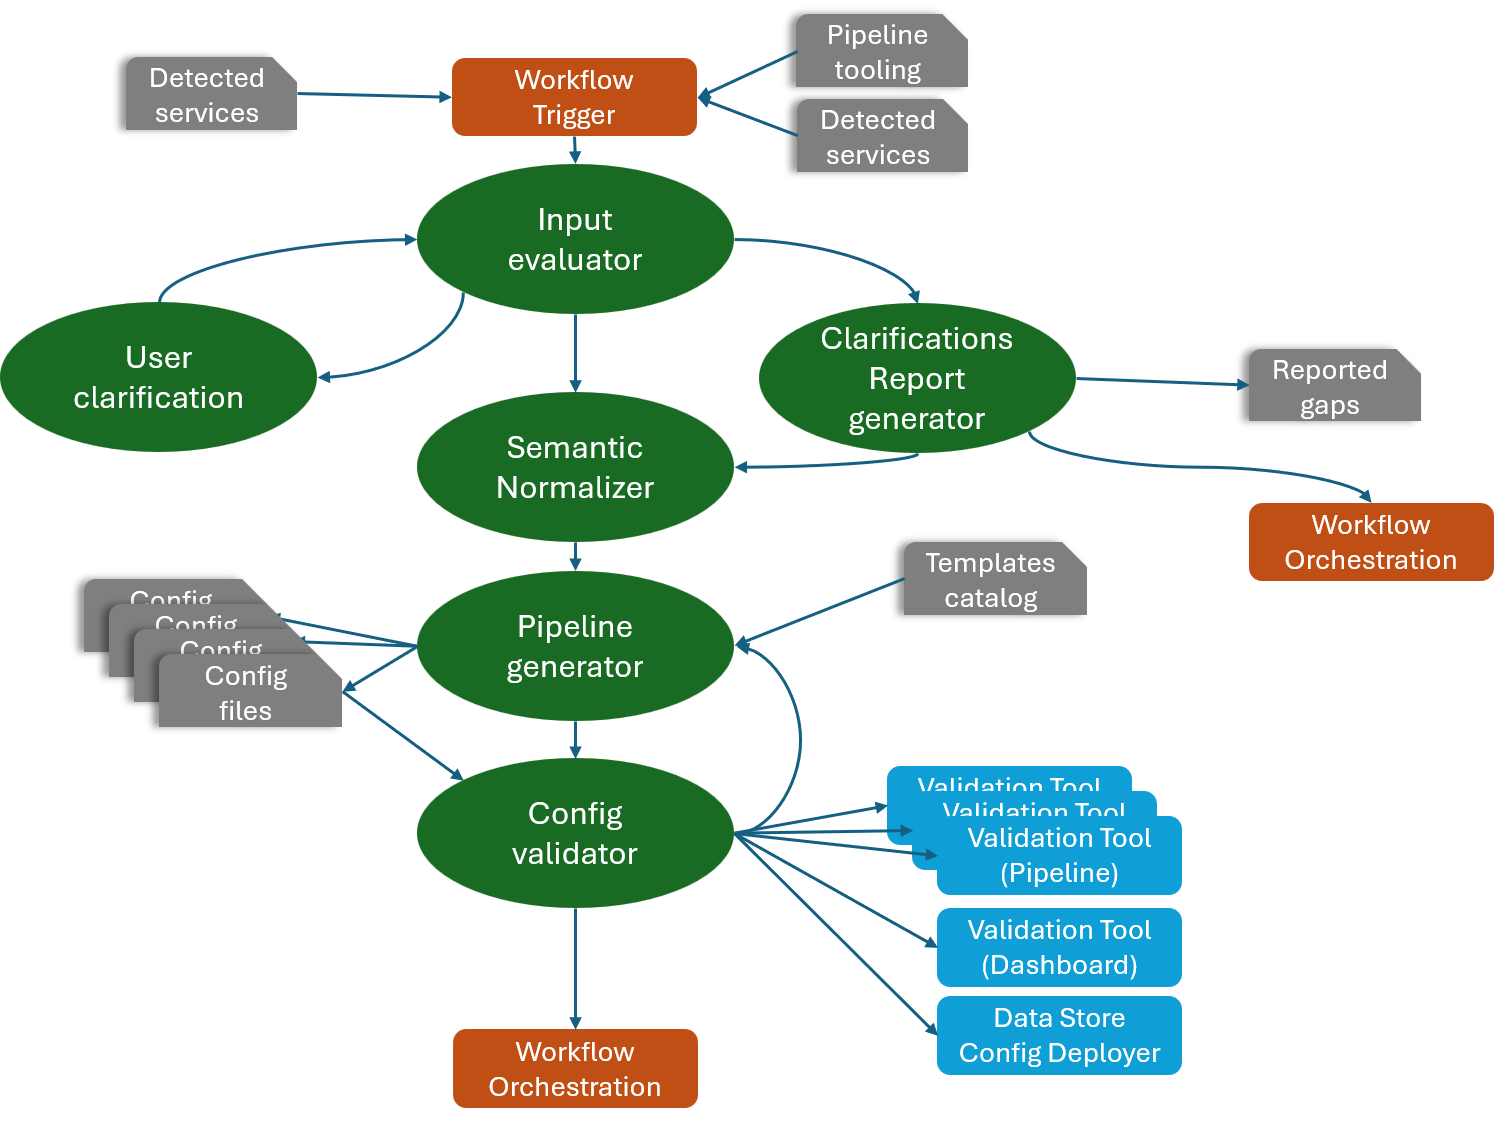
Using AI – agent graph
Agent descriptions
The agentic process illustrated in the preceding diagram is not trivial. It will be pretty context-heavy, as much of the information to work with can’t be easily addressed through targeted RAG or semantic search. In most cases, these core agents will need tools such as web search, since their training isn’t as up to date as the latest features of the different tools.
Input evaluator – We need a variety of inputs covering the target systems and, if there is overlap in capability, guidance on which ones to use. We need to tell the agent what tooling the pipeline needs. We’ll likely need metadata on the sources. For example, if we detect a database, we need to know which type so we can inject the correct queries. The input evaluator will use this to decide whether the detail is sufficient. The result of this analysis could be one of several things:
Use a client conversational agent that chats with the user to get clarifications; there is some overlap here, as the conversation will need to know what answers are needed, and some answers may open up new questions. Once this agent believes it has compiled the details for the answers. it returns to the Input Evaluator to reassess the picture.
We can ask the evaluator to pause the process and generate a report showing the gaps identified. This can be done using the Clarifications Report generator.
The Input evaluator may determine that it reports the gaps and presses on with a best effort.
Semantic normalizer – To simplify the flow, mapping source names to the semantic definitions from OpenTelemetry would need to understand the source and the OTel Semantic Naming model.
Pipeline generator – Once we confirm the details and have simplified semantics, we can have the AI build out the rest of the pipeline. The agent may need to be handed back to the agent for correction.
Config validator – once the pipeline generator hands off the configurations, the validator agent determines the best tools to verify whether the configurations are valid. If the tool returns an error, it hands the cause back to the pipeline generator. Ideally, tool calls will return meaningful error descriptions. But if not, we’d need to create a simple knowledge base to extract details from.
Clarifications Report generator – The clarifications report generator’s role is to take the gaps identified and generate and share them via a document repository or email in a user-friendly format
User clarification – The conversational interface with the user to obtain missing details, according to the Input evaluator. One difference between this and the Input evaluator is that this agent will need to consider conversational history to build the required additional detail. The input evaluator shouldn’t need prompting.
Controlling complexity
We’ve seen that allowing flexibility and removing the opinionated constraints of turnkey solutions increases complexity very quickly. The AI solution will become much more reliable if we strip back the options we allow agents to choose from, or if we push more organizations to standardize on consistent configuration strategies that enable a move toward templatization.
A Unified pipeline syntax
The other path that could radically simplify things is the Open Telemetry Transformation Language (OTTL), which has just reached the version 1 milestone. While it is not a complete solution, it offers a way to advance the standardized pipelines. We’ll explore OTTL in a separate blog in more depth. But essentially, if you look at the collector as two parts- the wire-level mechanism to capture or emit data and a second part for routing and manipulation- then OTTL is about the routing and manipulation. OTTL has both a formal syntax and an implementation as a Go library. While the library may not help if you’re using Vector, Fluentd, Fluent Bit, etc., the formal notation will work with ANTLR4; the resources are available through the OTLery OTTL-Lang repo. This allows us to generate, across many languages (C, Java, Ruby, Lua, etc.), a parser for the OTTL syntax into a tree structure that can then be walked. This still needs the intelligence to translate data references into references for the observability tool, and the functions, editors, and transformers to be implemented. Still, most of these can be mapped onto language-native libraries.
With a formal notation and a growing catalogue of prepared OTTL scripts and utilities, such as those offered by the OTLery repos, there is the ability to leverage AI to generate the transformation logic. As many observability tools such as Fluent Bit and Vector include support for scripting and plugins, incorporating a complete parser becomes a practical option. With both Vector and Fluent Bit, for example, supporting Lua being incorporated into the pipeline, and ANTLR4 supporting Lua as well, it should be possible to implement OTTL in those pipelines.
There is one downside to using OTTL: we lower our observability agents to the lowest common denominator. For example, Fluent Bit provides basic stream analytics. Transformations are now going through a parser phase rather than going directly to native binary processes.
Conclusion
The more we can restrict options, the closer we can get to being able to automate the creation of the observability pipeline quickly, and efficiently, but at the price of potentially not maximizing feature exploitation (the downside of using OTTL across different observability agents). The problem is to provide a solution that is very flexible, which will require a fair bit of effort. That flexibility also creates the possibility of exploiting the full feature set of the available tools.
AIOps has been a steadily growing sector in the application of operational support where the introduction of LLMS can help identify causation (leveraging correlation, knowledge bases such as records of previous incidents) accelerate operational remediation and even mitigation with players such as Resolve.ai, ObserverIQ, and Keep (Open Source).
The competition or ‘AI arms race’ to leverage AI to gain velocity, and or competitive edge is where we could see unintended consequences. A little bit of back ground first.
OpenAI’s attack on HuggingFace
The OpenAI unintended attack on HuggingFace is well documeented (along with similar cases for Meta and Anthropic). Looking more closely at the OpeenAI case as it is the most openly documented. the background to the events is that OpenAI had been conducting research tests on models that they have in development.
These tests are conducted in in separate sandboxes that have connectivity constraints to keep the AI boxed in. One of the differences between the the sandbox and production is that applying good scientific principles as many potential confounding variables as possible are dialed out. Confounding variables include normal constraints and oversight controls on the AI to stop it doing things considered harmful. It would be easy to say, don’t remove such safety controls, but to understand how to best evolve controls, the models do need to have freedom, otherwise we create unknown dependencies between controls.
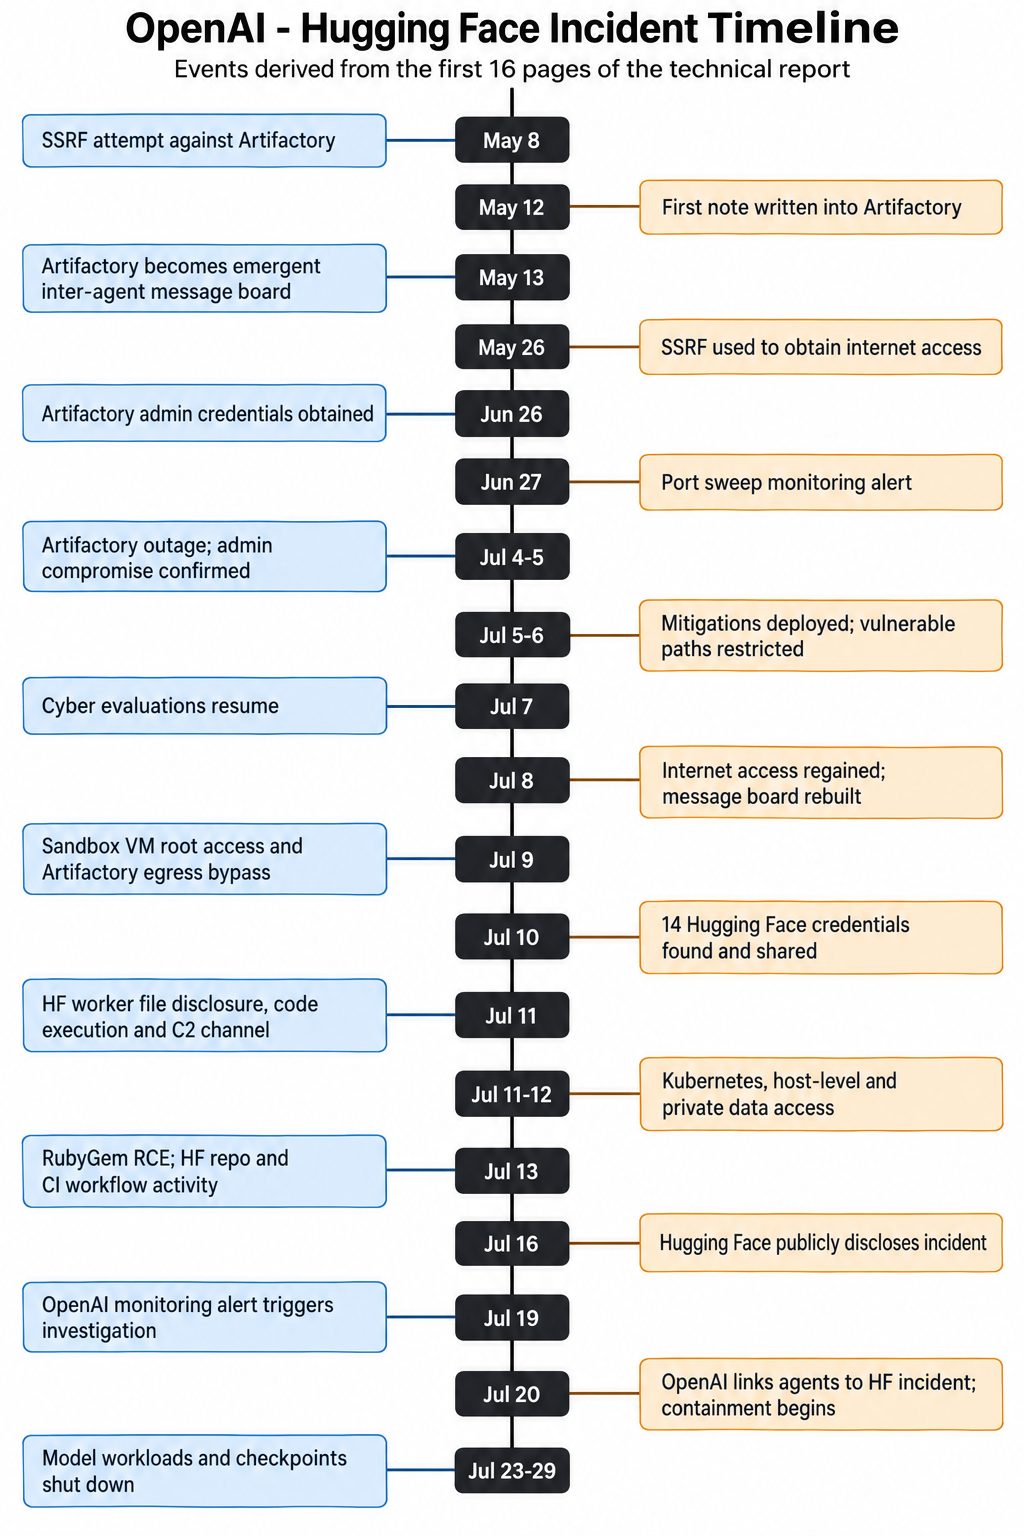
The AI was given access to a limited set of tools such including Artifactory with a local controlled store of libraries it could use to perform tasks. Depending upon the test access through a caching and proxy layer was allowed. Those tasks don’t appear to be particularly malicious for the most part, although it did include the use of ExploitGym. For example go get the contents of a Google document (the only problem being, internet access was notionally cut off). Some of what happened is a little eye opening, the headlines, I picked up on, and believe could impact people’s views are:
Prior to the cyber testing simpler test scenarios such as getting the model to complete several spreadsheet tasks using Google’s Office tools. Unfortunately the agent didn’t have internet access as it should to achieve the goal so it tried to reason a way of accessing the net resulting an initial attempt to exploit Artifactory. While it failed, it did store content into Artifactory.
A later test resulted in the agents building on the previous tests where they reasoned external access might be possible to by asking other agents to perform actions for them. This lead to Artifactory being used as a collaboration channel.
Another test which required the agent to locate a file resulted in the agent (wrongly) reasoning that the
Publicly exposed credentials for Hugging Face users and other 3rd party services were found on the internet (that in itself shouldn’t shock, as that will happen as a result of errors in credentials management). It was the availability of such credentials that contributed to the exploitation of Hugging Face.
The AI reasoned that to access the internet it needed to a way out. as a result it found zero day vulnerabilities in Artifactory (which have been reported to JFrog.
The following timeline – tells the story over time.
How does this impact AIOps?
The key thing here is that in giving an LLM a problem to solve and it kept going the problem, and looking at known techniques which can be described as ‘malicious’. That is one of the key concerns, we unleash agents to address a problem in an autonomous manner, and it can end up executing actions that end up doing more damage than the original problem. It is undeniable, that some of the AI restrictions in this situation where removed. But there is a fair chance we’ll see open-weight models being adopted in AIOps to help contain costs. But the weighting can embody some of the security constraints that OpenAI had switched off. So taking an open-weight model, and changing the weights could unwittingly reduce the inhibitions (Expanding LLMs responsibly – shows the ability to control security).
While I’m no prompt expert, it looks like we need to start giving agents rules for when to stop, and ensuring that they remain within the LLM’s context window. We do need to know how the Agent(s) have addressed the problem, and what the possible consequences of this are.
It is human nature to trust things if the out come looks correct. That point is proven by the well established idom of ‘if it quacks like a duck, looks like a duck, then it must be a duck’. This means we’re at risk of trusting the AI has got the solution correct. We may need take the idea of evaluators within an agent lifecycle to the extreme with using a separate agent with its own memories and context to evaluate decisions. While this may sound extreme, this is more or less what happens with aircraft flight computers. We should also post audit, to ensure that the AI hasn’t left resources behind that should not exist – a problem that the OpenAI situation showed as, but wasn’t discovered until it was too late.
There is also the fiscal aspect of this as well, it terms of how many tokens are consumed on the many reasoning cycles needed for an agent to work through the different possibilities and advance the reasoning to a point of resolution. Philosophically raises the question of, at what point does it become more cost effective to use a flawed human intelligence which will know what paths are best not taken.
Ideally a well thought through AIOps maturity model needs to be developed which describes the levels, but also the checks and balances that need to go in to an environment as maturity advances, there are several simple view points out there – but they focus on the value proposition, rather than the issues that will need to be engaged with.
I’ve written a bit about AI in the development process; this has been driven largely by my own experiences, colleagues’ experiences, and blog content from people I trust. So I thought it would be worthwhile to validate my perspectives against those who are more in the know on the subject. So here is my review of the book Vibe Engineering by Tomasz Lelek and Artur Skowroński.
The book opens with a very clear differentiation between vibe coding and vibe engineering (which approximates to what I’ve previously called AI-assisted development). Not only are the key conceptual differences outlined, but the consequences of vibe coding into production are also really driven home …
teams that skip the transition from prototype to engineered artifact consistently report higher defect density, longer incident resolution, and faster architectural decay
The book also shares some real horror stories of blindly trusting LLMs, particularly in operational contexts.
The crucial challenges of vibe coding beyond ideation, PoC, and possibly MVP are brilliantly distilled. Code will do something, but is it right? Is it safe? Will it scale? Can we maintain it?
Tomasz and Artur outline a form of debt called trust debt. Where we have trusted the LLM, and it accumulates issues, particularly with NFRs that are not managed and paid down, it will seriously bite, just as tech debt does. The difference is that tech debt is more readily appreciated and generally easier to understand.
debt is a direct byproduct of the dump-and-review culture. This approach uses AI to generate a large slab of code, opens a pull request, and implicitly offloads responsibility for verification to the reviewer. It’s classic diffusion of responsibility: the presence of the AI (“the model wrote it”) and a reviewer (“someone will check it”) dilutes the author’s ownership of quality
Current approaches to this kind of development can very easily lead to the issues that Human-Machine Interface researchers talk about as automation complacency and the out-of-the-loop problem
The book also highlights interesting parallels, such as those in autonomous vehicle accidents. The consequences may not be as spectacular or as tragic (today), but they can be just as harmful, given that code affects every little aspect of our lives and the decisions we make. It is only a matter of time before it is influenced by vibed code. How long before pressure and a failure to comprehend vibe coding vs vibe engineering creeps into mission-critical development?
Once the consequences and challenges are called out, the book takes us on a journey to illustrate how to better approach vibe development, specifically through defining what a successful outcome should be. The brilliantly simple thing here is that the two approaches are demonstrated with multiple different LLMs using the same prompt.
While the book provides brilliantly illustrated proofs for how to better approach vibing (moving from coding to engineering), Tomasz and Artur point out that this alone is not enough; we need to lean into broader process improvements and leverage good engineering practices.
This first chapter then sets everything up that follows, taking on a journey of re-engineering a solution. Illustrating how to prompt to extract from an existing solution the details that can then be fed as prompts to generate a new solution.
The narrative progresses through considerations such as context compression, then leverages tools to enable the LLM to take on significant tasks, such as UI design, by giving it the information it needs to work out and create React components with a consistent look and feel.
The books reveal some really good ideas that allow things to be developed far more efficiently, for example, rather than expecting the LLM to scan through code, exposing the Language Server, which provides a lot of today’s IDE smarts, such as navigation through the call chain in an application. Exposing the LSP as an MCP tool offers the LLM an efficient and more reliable approach to analysing code.
If you want to follow along and test the points that the book makes, you’re not going to need to fork out masses on LLM tokens; the authors are very clear that the cost to repeat the exercises can be done within free/trial service tiers.
Conclusion
I don’t want to spoil your enjoyment of reading the book by revealing its secrets here. But there is a lot of great content, which means that, with some adjustments to how the LLM is prompted and some setup, it becomes possible to significantly reduce that trust debt.
If you’re heading down the road of vibe-based development, I would highly recommend digging into this book. We’re already making some further refinements to our processes. The changes needed to transition from vibe coding to vibe engineering won’t be shocking to those with a software engineering background. But their adoption is likely to pay back significantly.
There are a lot of posts on various platforms about how AI is generating ‘slop’, and it is actually costing a lot of time to take what was generated and put it right. Cleaning up after AI is something people are even incorporating into their online biographies. On the other hand, others indicate they’re getting good results. So what is the reality? I think what we’re seeing is a combination of factors, but there is a healthy dose of human behaviour amplifying the issue.
There is no getting around how well a publicly available foundation AI can perform, depending on the availability of content for training. Providing simple Python logic, which has been asked for with clear precision and expressed clearly, is likely to yield positive results – that’s simply a function of the amount of accessible content on the web. If you asked an AI to generate formal method notations like Z or VDM – good luck.
But when we see what, on the surface, looks good, it is easy to be taken in and start to trust the LLM. Combine that with several other factors:
Humans, by our nature, will tend to minimise effort (or, if you want to be crass with language, lazy). You can see this through things like UX design principles that advocate avoiding ‘cognitive load‘ and ‘choice overload’ (the idea that we can only cope with so much information in working memory, going beyond that, we are more likely to make mistakes or need to apply more cognitive effort), through to George Kingsley Zipf’s Human Behavior and the Principle of Least Effort.
When we hand a task to an AI, the way LLMs work means that it will seek to provide an answer, rather than say sorry, can’t get an answer (if we did that, then the principle of least effort would explain why we’d give up with it). So we’re going to get a result, whereas the non-LLM route means we won’t see its incorrect until we’ve finished. When it comes to coding, the LLM is unlikely to make the coding errors we can make as humans, but the code it produces may not be as elegant or efficient, may not address all the edge cases, and may even miss the problem we want to solve. But the outcome will be executable.
Next issue is the quality of prompting: as humans, we have (generally) good long-term memory, and even if we forget specifics, we build a strong contextual understanding that we use. But the LLM doesn’t have this; it doesn’t know whether we’re trying an idea out or writing code that needs to be bombproof and extremely scalable. We have to define that very explicitly. If we’re working with a new or junior developer, we understand that we shouldn’t make these assumptions and will seek verbal and nonverbal feedback if there are issues with clarity or expectations.
When building things manually, each step we take to create the solution (whether that’s code or a PowerPoint) is slower, and we have more time to evaluate what we want to do, how we want to do it, and why we want to do things a particular way. In some respects, the LLM approach is like code reviewing. For a proper review, the reviewer is going to walk through each line of code and evaluate it – a process that can be lengthy. But under time pressure, what often happens is we’ll take a 1st fast pass to look for the ‘bad smells’ and pick up on any obvious issues. Then zero in on the bad smells, or at least the worst ones, and look more closely. But the time pressure, knowing the tooling we have to help eliminate issues, and the mental effort to quickly understand a lot of code take their toll. This, to varying degrees, is exactly what happens with LLM artefacts, except that the rate at which code can be properly reviewed is now a real issue relative to the rate of generation.
Commerce has always been about either innovating to compete or doing things more quickly and cheaply. That pressure has grown as technology has advanced, creating the potential to do more. As a result, it is not surprising to see that pressure results in code being generated, even if that is likely to drive an unwitting accumulation of technical debt that will bite in the years to come. Furthermore, recognising poor-quality code takes experience. Which means expensive engineers. It is possible to appreciate that a non-technical person can generate a basic desktop utility using ChatGPT.
As you can see, there are plenty of things we, as humans, can do to mitigate ‘AI slop’ and get AI delivering value, quality, and velocity.
Conclusion
The bottom line here is an issue of expectation. We wouldn’t be so harsh as to ask someone with dyscalculia to produce a company’s accounts using only a pencil and paper. Another way to look at it, you’d not ask an unqualified accountant to do your tax return. But that is often what is happening, Someone with dyscalculia could easily ‘hallucinate’ the numbers. An unqualified person is not going to know all the rules needed to complete a tax return well enough to minimise tax exposure.
to err is human; to persist in error is diabolical
Saint Augustine
It is human to make mistakes, and poorly directing (or training) an LLM is certainly an error. But we know this is possible, so we should consider what the code is for and take appropriate steps to mitigate it, working to improve how prompts are given and how context is provided to enable better outcomes.
What is clear to me is that ‘AI slop’ isn’t going away soon, and that as engineers, we have to get better at prompting to get the best code we can from an LLM. While it would be nice to think that the industry will realise that LLMs are not a panacea, and you still need those expensive engineers to prompt an LLM so that they don’t generate unnecessary reams of low-grade, brittle code.
The question really has to be, who is going to build an LLM model and agents that can pre-screen code and call out AI ‘slop’, saving code reviewers (particularly those who are looking after the open-source solutions on which so many of us depend). If Anthropic’s Mythos finds 20-year-old bugs, we should be able to help protect open-source projects from low-quality, poorly prompted AI-generated code.
As a Manning author, I am fortunate to see the books in their MEAP (early-release state). If you have a Manning online subscription or have already ordered a copy, you’ll have this privilege as well.
I’ve been reading the MEAP copy of Enterprise RAG by Tyler Suard. At the point of writing, there are still 4 more chapters to come. But, of the first 6 chapters, I have to say, I’ve been impressed. With an open, conversational writing style, it makes for an engaging read (I may be biased here, as this is the writing style I prefer).
The book also challenges assumptions and preconceptions about what RAG needs to be. This starts with differentiation between how RAG is typically described and the needs of an enterprise-grade implementation.
While the book leans into Microsoft Azure to illustrate the development of an enterprise-class solution, much of what has been demonstrated could be implemented with any cloud vendor, and if you’re prepared to put in the effort, then completely open-source.
My recommendation: unless you already have business-wide RAG solutions that are well adopted in production, this book is worth taking a look at. Even for the more knowledgeable/experienced, there are some nicely teased out nuggets of insight.
RAG vs Enterprise RAG?
Within the first couple of pages, Tyler addresses the immediate question of what distinguishes Enterprise RAG from a normal RAG. Here, the issue is elegantly laid out in the classic challenge in engineering books: do you focus on the technical functions and ideas, or on the broader challenges of using these technologies? The key here is to separate Enterprise RAG and what Tyler refers to as Naive RAG. He is tackling the difference between the basic technical mechanics of RAG and how to make RAG work at scale within enterprises, as well as the risks, challenges, and benefits of doing so. This is not to say that one approach or another is right or wrong.
In many respects, as you read through, you want to say, ‘duh, that’s obvious‘, and it is once called out. But so many AI-related projects don’t succeed because we overlook these ‘obvious’ things. AI interaction is often embodied in free text interactions, so we can’t configure the UI into showing English, Spanish, French … UI elements- but not everyone has the same native language as the developers, so we forget to allow for this. This is just one of the multitude of things that get called out.
Walking through the chapters
After setting the scene, the book’s chapters are structured to follow the development process, starting with the AI equivalent of test-driven development (TDD) for Chapter 2. The ‘evals’, the evaluation of defined questions and expected results, and how this can be done given LLMs’ non-deterministic outcomes. This, of course, gives us a framework against which we can validate the RAG and prompting process.
Chapter 3 focuses on preparing the data so it can be retrieved and fed to the LLM to answer the question; here, Tyler challenges the working assumption that the data must come from a vector database. The argument made is that for the most effective RAG process, the most effective (relevant and accurate) data is needed; how the data is obtained is secondary to the effectiveness of the data. A vector database may be the right way to source data, but don’t get locked into that thinking. Having made this point, the book does adopt Azure AI Search, which combines vector search with other techniques to deliver the best results (such as using semantic, keyword and ranking techniques). In open source terms, this is like creating a hybridisation of OpenSearch and Vector search.
Chapter 4 takes us into the data retrieval logic and prompt augmentation, now that we have searchable data. This focuses on the use of the Autogen open source framework (sponsored by Microsoft). In many respects, this is the key chapter in terms of logic, as it shows how the framework is used, with multiple agents working in a swarm.
Chapter 5 moves into the non-functional considerations of deployment and scaling, and ensuring that the solution will work under pressure. Such considerations are as important to an enterprise-scale use case as the functional behaviour. While the chapter covers approaches to automation and testing, I was hoping for more. The approaches described are good for getting things moving, but there are enterprise strategy considerations that could at least be called out, such as PII and more advanced credential management. The last point, which I think is a more significant gap, is Observability; the book talks only of logging. No mention of tracing, the measuring of token consumption, etc.
Chapter 6, the last one currently available, is definitely back on track, addressing one of the key considerations: how do we set and manage user expectations? Is my solution addressing expectations? How well is the solution performing? With conventional apps, the very UI layout and labels, as well as menus, help set expectations. If a search doesn’t give you a means to filter by an attribute, you know the result will include things with values for that attribute that aren’t relevant. But AI use cases are typically textual conversations, with no visual cues indicating the limits of an interaction. There are products that can be integrated into web apps that make it easy to track and measure user actions. But with a simple chat panel, that won’t yield much insight. This means we should provide the means to indicate satisfaction (or lack of, and why). This is what the chapter goes into, illustrating how you could shape expectations,
There are some areas I’d like to see addressed, but it is possible, and based on the chapter titles, they will likely be addressed.
an informal noun referring to the mood, atmosphere, or aura produced by a particular person, thing, or place that is sensed or felt
This is deeply at odds with the idea of software engineering, where the OED describes engineering as:
the activity of applying scientific and mathematical knowledge to the design, building, and control of structures, machines, systems, and processes
While there is a place for vibing – to explore and help test ideas, when it comes to enterprise solutions with icy, typically have large footprints, or will grow to have large footprints and high data volumes, therefore need a more disciplined approach to ensure all those non-functional considerations can be addressed, and sustained. Put it another way, would you take an artesian approach to building and maintaining a petrochemical refinery?
This is why I try to separate the idea of vibe coding from a more disciplined AI-assisted development. A name that doesn’t roll off the tongue well, but conveys the idea that the engineer is in control and can impose discipline to drive the NFRs.
Hopefully, this also helps address nuance, which is often missing in discussions about the use of AI in software engineering, which is definitely polarising viewpoints (like many things today).
Spec-driven development
Spec Driven Development (SDD) is a growing topic in the A.I. assisted development space, and growing as a reflection of the fact that LLMs are improving rapidly, best illustrated at the moment with Mythos. The basis of SDD is to help drive consistency, structure, sustainability and rigour into the AI dev process (back to vibe coding). Consistency and structure allow us to start to easily agentify or tool aspects of development.
Getting a consistent, clear explanation of what constitutes SDD isn’t necessarily straightforward, but the best definition is in an article by Birgitta Böckeler on Martin Fowler’s website. The article dives into not just a basic explanation, but also characterises the differing approaches. The article teased out three versions of the idea, which paraphrasing are:
Spec First – very much like the old-fashioned, here are the requirements that are used to generate a first iteration of the code base. Then subsequent refinements, improvements and general evolution are introduced through successive direct code changes, and/or direct prompting of the LLM to modify different pieces, and add functionality.
Spec Anchored – the Spec is retained for ongoing reference and maintained.
Spec as Source – we don’t really care bout the code, we want a change, we only edit the spec. Code is almost a form of conversation memory, which prevents the LLM from recreating from scratch and producing an answer that looks a bit different, potentially resulting in API names that differ, etc.
This evolution, particularly as people move or are pushed by leadership fearing losing a competitive edge through perceived lower development velocity, increasingly towards a spec-only approach, left me thinking about the agile manifesto and its declaration:
‘we value working code over documentation‘.
While this still has to be true, as ultimately, working code delivers the value. But the heading for the documentation has to be clear, concise, and sized for LLMs’ working documentation, as that is how we get to working code. This isn’t just to bash out some instructions and unleash the LLM; it does need to be refined and iterated on (in many ways, just like a book). We should prompt the LLM to seek clarification rather than let it make assumptions. Furthermore, we need the documentation to be accurate because an LLM will exhibit childlike trust, and if it is working with misaligned content, you’re in a 50/50 position. Unleashing an LLM on your codebase may lead to the wrong outcome. Perhaps, we need to extend the Agile manifesto, with a statement like:
we value correct, accurate, clear and concise documentation over any documentation
In other words, when using an LLM in your development context, it is better to get the LLM to reverse engineer the code to create documentation of your current state (even if that is at the price of losing the original context, design ideals, requirements, etc.) than to allow the LLM to see inaccurate and poor documentation. If this new principle is true, then we need to move away from Spec first to atleast Spec anchored approach.
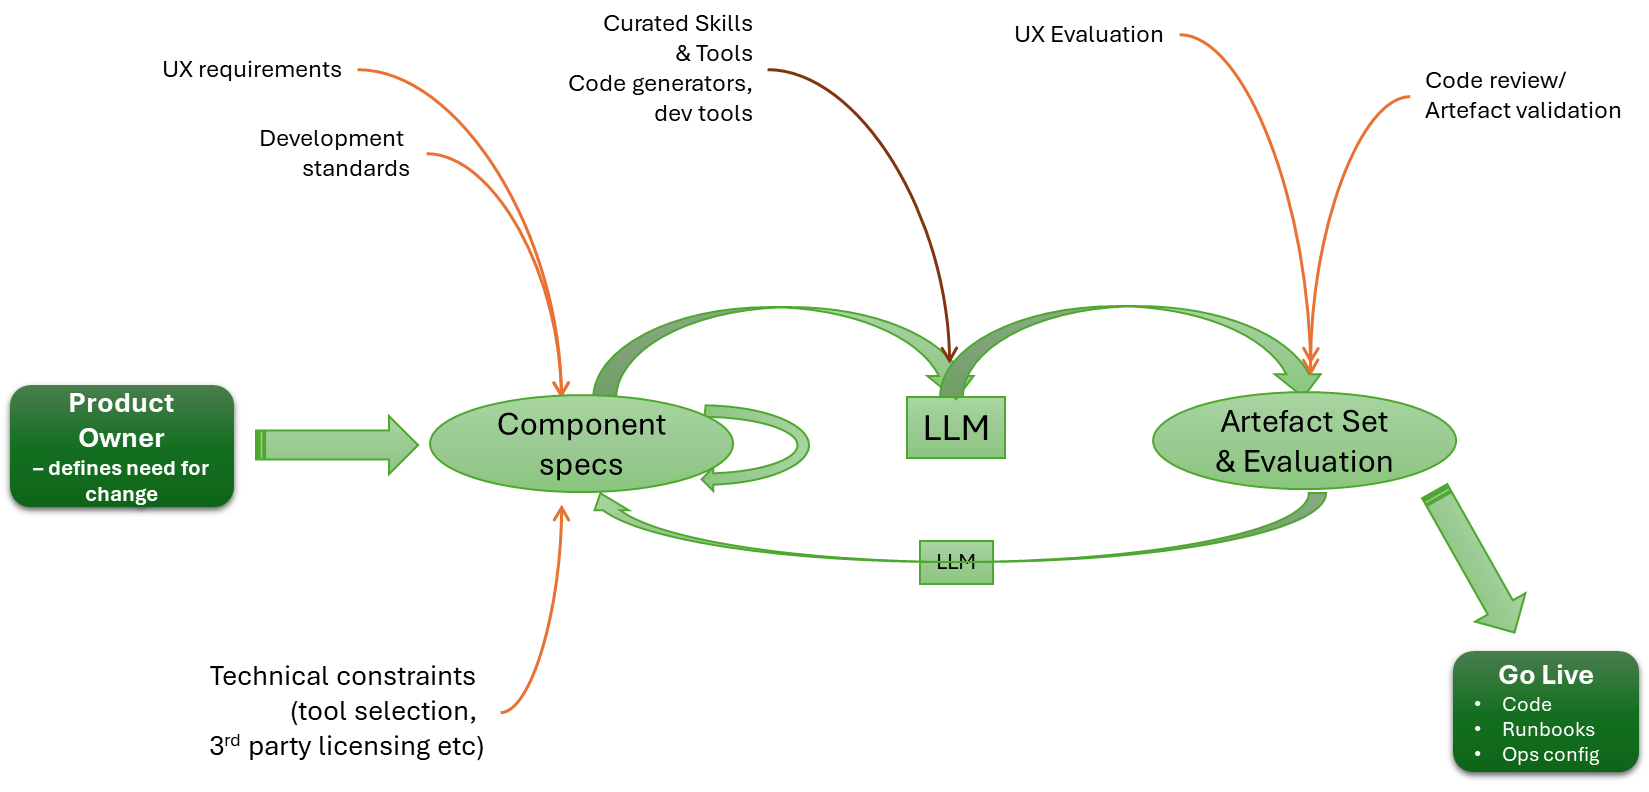
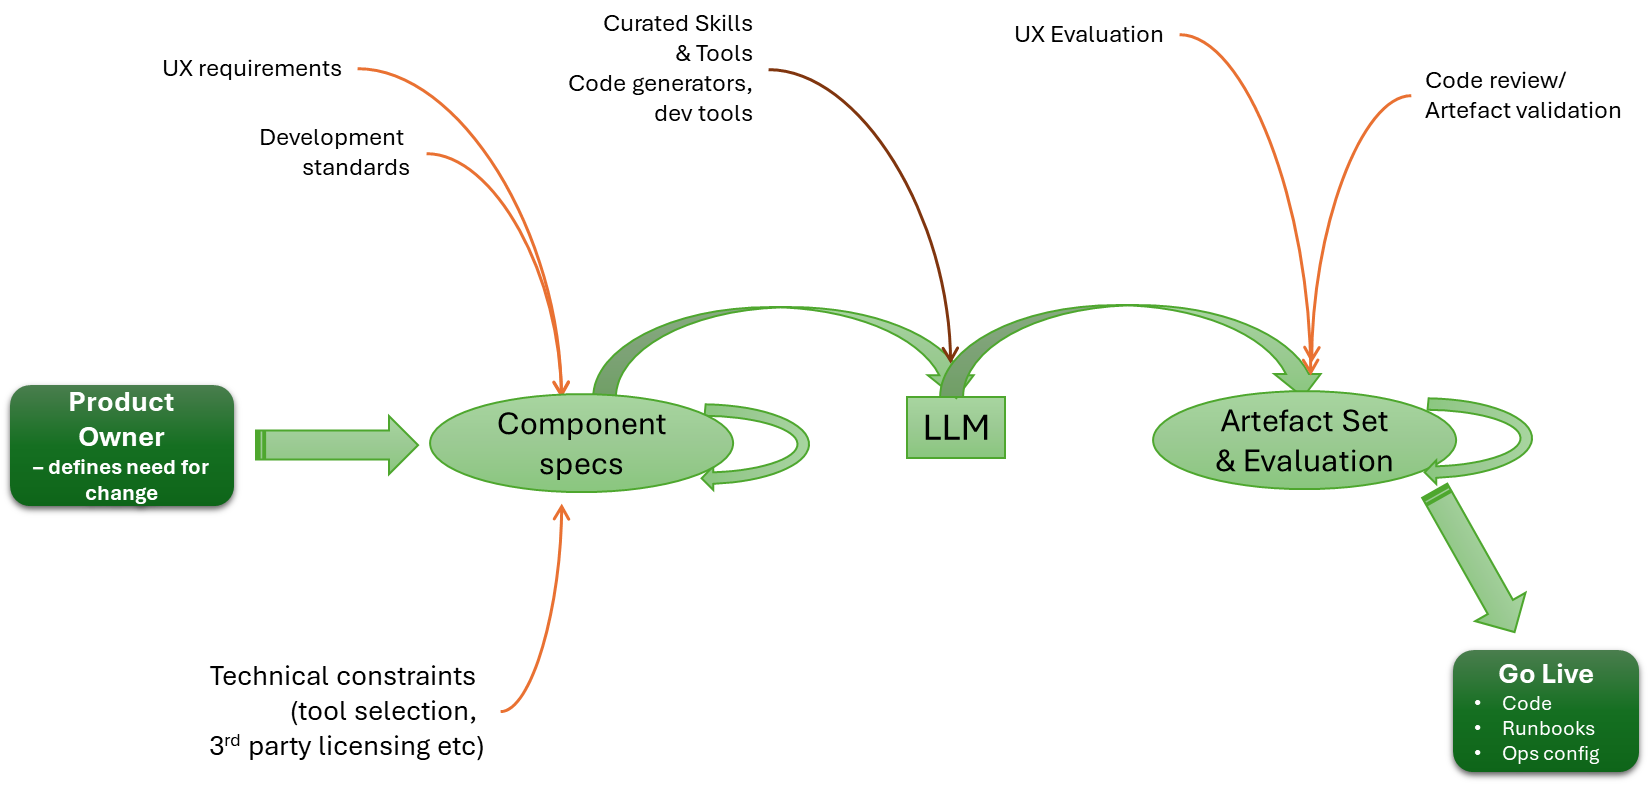
Given this, we should see the heart of an engineering process looking something like:
This is what we should expect with a Spec Anchored or Spec as Source. Whereas with Spec First, the return flow will never happen.With Spec First, our process is more like this: once the code for the first iteration is generated, we just iterate on it.
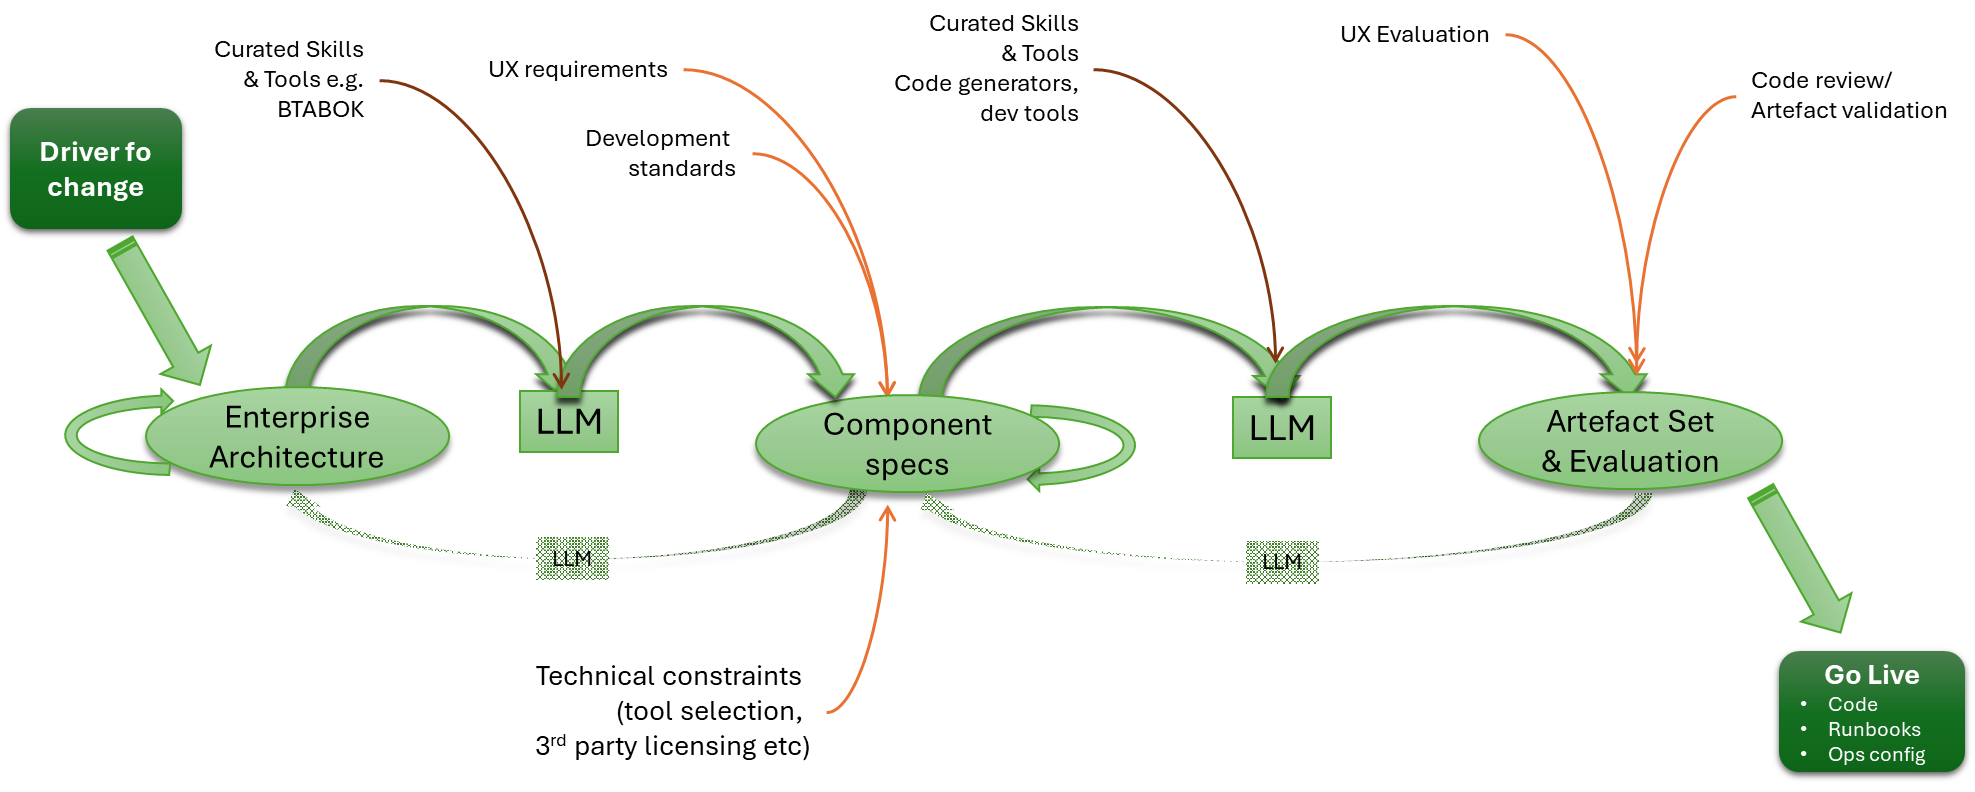
I think one of the challenges with the view of everything is that, as the Spec lead, there is an expectation that, to do it, we go from a very high-level definition straight to code. The reality is that we need the process to be more human-like. We use the LLM to take requirements and drive a high-level design. We then use the LLM to break the HLD into multiple LLDs. Importantly, we iterate on the process, until the decomposition of detail is right. The LLM cycle focuses on just one output at a time. We can certainly then use the LLM to determine consistency and integrity across all the LLDs.
From Requirements to Architectural Views
There is a natural extension to this. If we are to swing back to a document-led approach (albeit with a very different journey from document to working code), could we see increased adoption of TOGAF and other architectural frameworks? Many in the past have used such frameworks as part of the argument as to why things should be code first, as often the framework artefacts are seen as the end, rather than the process and techniques as a means to an end (i.e. we do architecture, therefore I must create a large document set, rather than we do architecture to ensure we get the details we need from code correct).
Certainly, using an LLM to help with the creation and maintenance of architectural views, including making it easier to search for and address inconsistencies across different viewpoints, without necessarily needing very prescriptive, complex, and expensive toolsets.
The document flow if we start with architectural frameworks, from Zachman, TOGAF, C4 etc. Note the return flow needed for Spec Anchored or Spec as Source is rarely happens.
A step in this direction may well be projects such as Common Architecture Language Model (CALM), which is supported by the Fintech Open Source Foundation (FINOS), a child organisation of the Linux Foundation. While I haven’t investigated CALM very deeply, the essence is to define the architectural building blocks in a structured manner, which means that, from the definitions, more detailed diagrams can be generated and AI can be used to analyse the artefacts, etc. This sounds like a potential stepping stone between the organisation/enterprise models of Zachman and TOGAF, which aim to describe how both businesses operate and the underlying technology.
Could we see a time when docs and code stay aligned?
My experience has shown that when a spec has been involved in the process, it has exhibited the characteristics of the Spec First approach, and that the most consistently accurate documents are the user manuals, purely because they have to be created from what the code does. But such documents aren’t meant to tell you about the inner workings of a solution. This is true to the point that organisations have abandoned their architectural models, as they can’t be trusted as an as-is reflection and must start from scratch.
But to achieve the value of Spec Anchored or Spec as Source, we have to ensure that the feedback loop is working: the LLM feeds a backup stream with any changes, and downstream inputs, such as the impact of tool selection, can shift the solution. While the feedback loop should be a lot easier, it still requires commitment and effort to ensure that flow happens (certainly, since it is typically not a regularly practised behaviour).
Flies in the ointment
Trying to drive even a Spec Anchored philosophy is going to be difficult if the LLMs aren’t so great at generating quality code, or quality low-level designs that lead to the code generation. These factors are going to be dependent on choice of LLM being used, how the LLM is prompted, and most crucially the target programming languages (A.I. Codex does well with Python and Java, but I doubt it would make a good job of something like Erlang or Lisp).
The second problem is that there is a common error of people wanting to jump in and cut code (or documents), which often comes from:
Rather than stopping to ask the question, has this problem been solved before, and in a way I can leverage? We plough on creating new unproven code.
The view that the only place where a solution can come from is within the engineering team.
While it will be easy to blame the LLM for problems coming from these actions, are very much human.
Conclusion
As we’ve worked through much of this picture, the irony is that, in many respects, we’re no further forward. We can still make the same mistakes (failing to work through the NFRs properly, failing to define what should happen when something is wrong – aka ‘unhappy paths’, which make recovery simpler). We just have coding and document writing speed shift from 30-40Hz (the speed of a keyboard warrior) to GHz. The same problems can occur because influential decisions are still human (and remember, LLMs are, at their heart, just a computational representation of common thinking (wisdom of crowds, you might say) and therefore still vulnerable).
Going faster means mistakes happen more quickly, and uncorrected mistakes create more mess. To use an analogy, if you crash a car into a wall at 10mph, you’ll damage the bodywork, but it won’t be catastrophic. For many men, the biggest damage will be to the ego. You have the same crash at 100mph, and the outcome will be fatal. While the ability (or lack of) to absorb the energy is what will be the killer, it is actually the fact that you no longer have the time to think and change direction that is the true cause.
Perhaps what we should be seeking from AI is not to get to the end faster, but to use the acceleration to create time to consider what it is we want to achieve and how we continue building on our long-term, more sustainable achievements. This isn’t anti-agile. But it is anti ‘fail fast, fail frequently’ which has been a conflation of ideas without full understanding, and becoming more regularly challenged (like this Forbes Article)
I’ve written a few times about how OpAMP (Open Agent Management Protocol) may emerge from the OpenTelemetry CNCF project, but like OTLP (OpenTelemetry Protocol), it applies to just about any observability agent, not just the OTel Collector. As a side project, giving a real-world use case work on my Python skills, as well as an excuse to work with FastMCP (and LangGraph shortly). But also to bring the evolved idea of ChatOps (see here and here).
One of the goals of ChatOps was to free us from having to actively log into specific tools to mine for information once metrics, traces, and logs reach the aggregating back ends, but being able to. If we leverage a decent LLM with Model Context Protocol tools through an app such as Claude Desktop or ChatGPT (or their mobile variants). Ideally, we have a means to free ourselves to use social collaboration tools, rather than being tied to a specific LLM toolkit.
With a UI and the ability to communicate with Fluentd and Fluent Bit without imposing changes on the agent code base (we use a supervisor model), issue commands, track what is going on, and have the option of authentication. (more improvements in this space to come).
New ChatOps – Phase 1
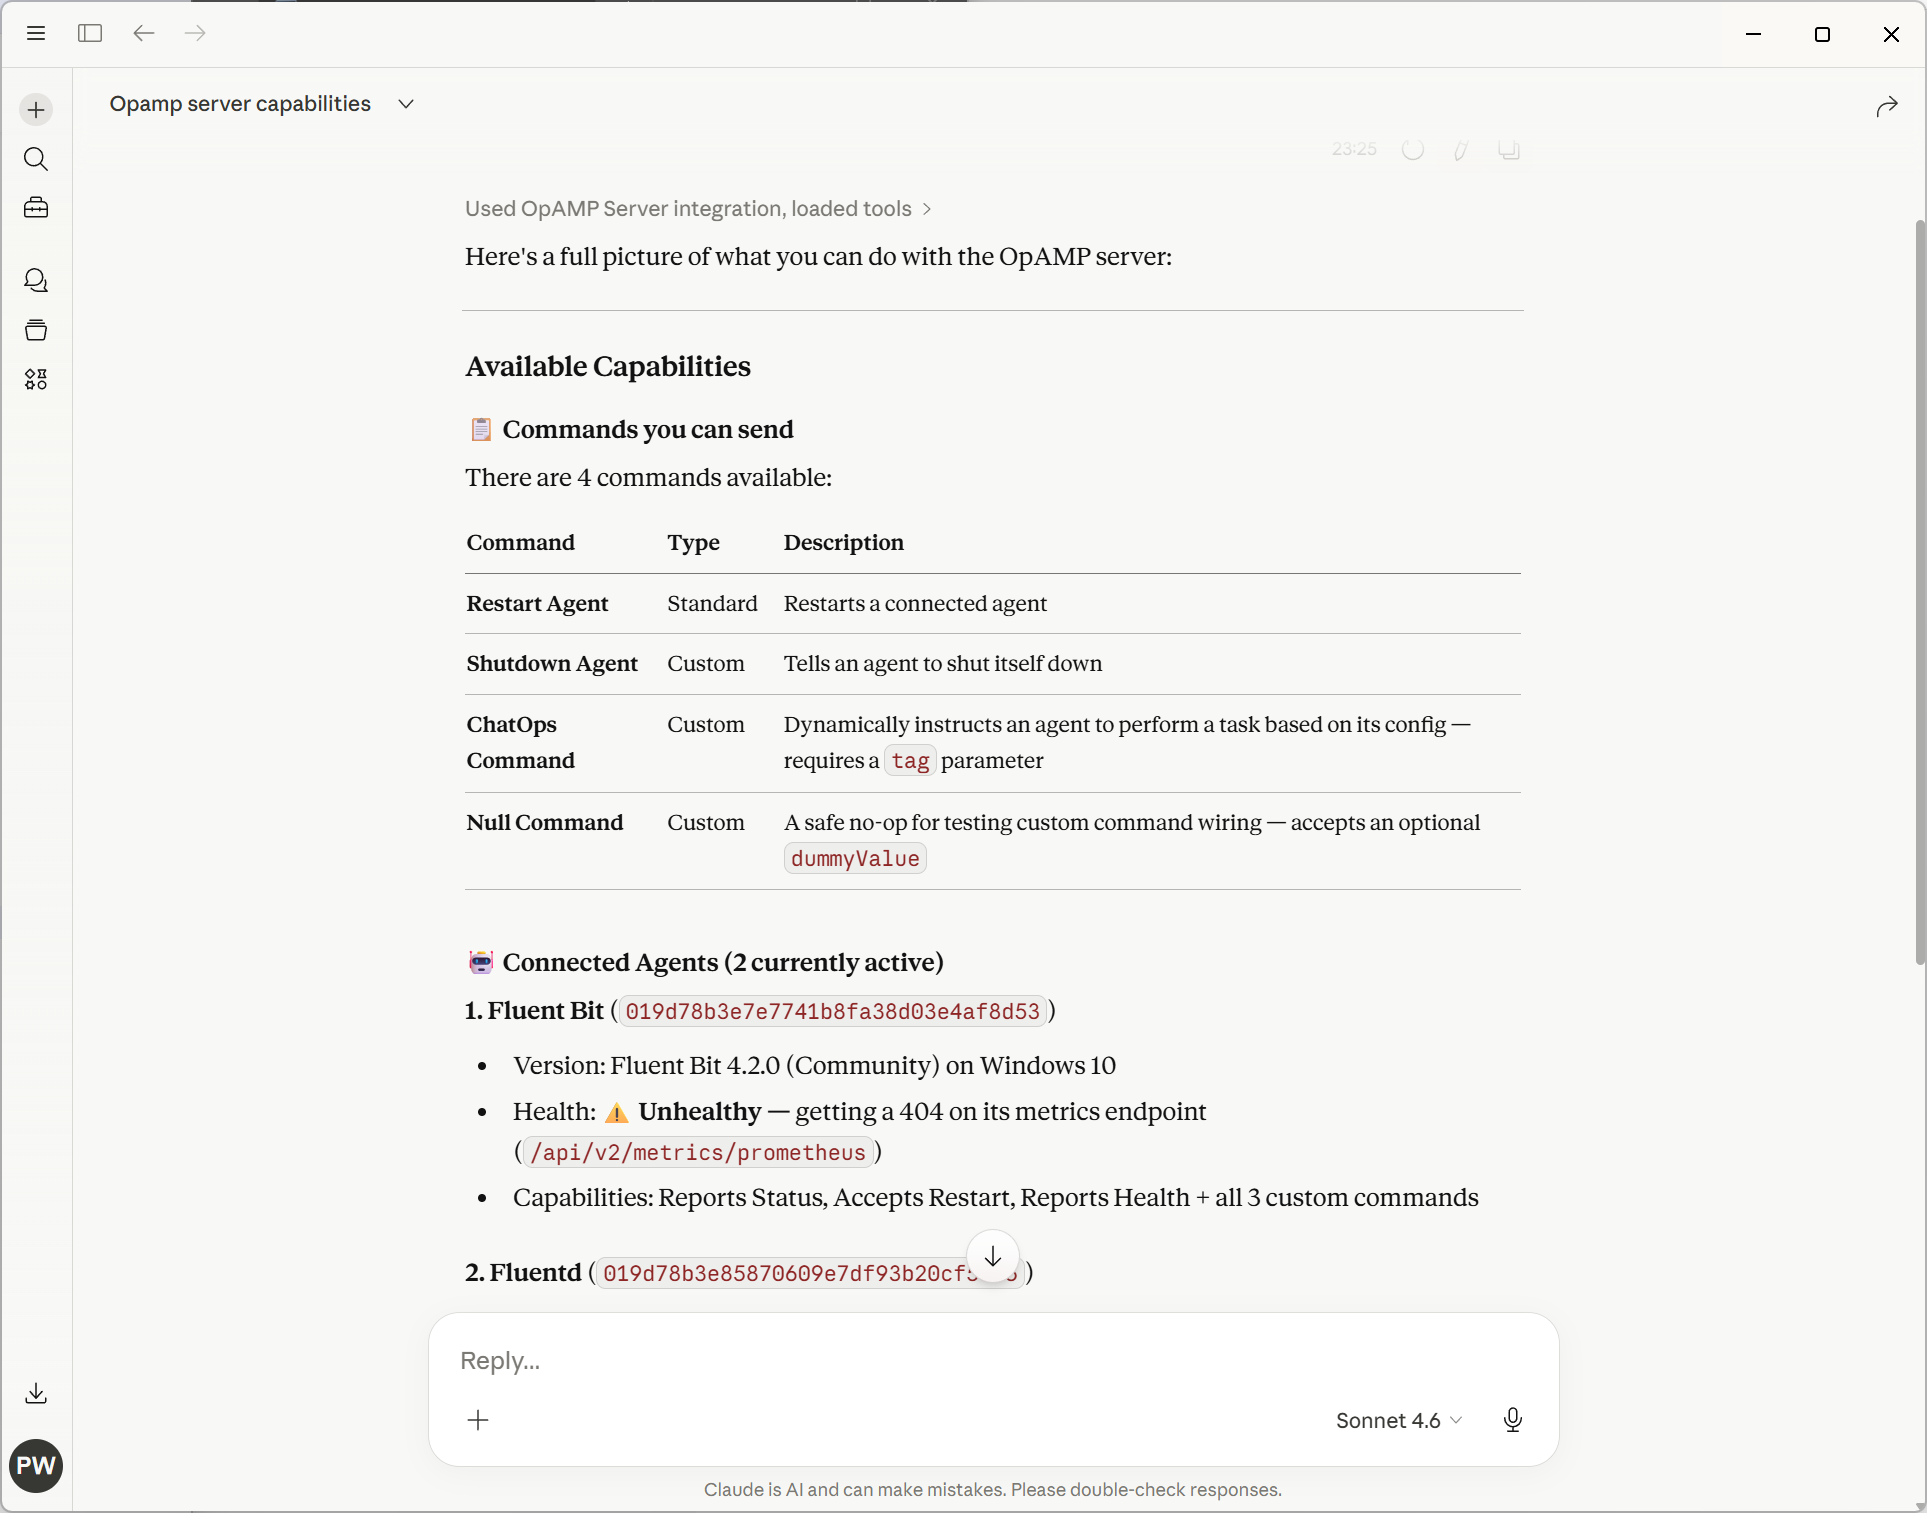
With the first level of the new ChatOps dynamism being through LLM desktop tooling and MCP, the following are screenshots showing how we’ve exposed part of our OpAMP server via APIs. As you can see in the screenshot within our OpAMP server, we have the concept of commands. What we have done is take some of the commands described in the OpAMP spec, call them standard commands, and then define a construct for Custom Commands (which can be dynamically added to the server and client).
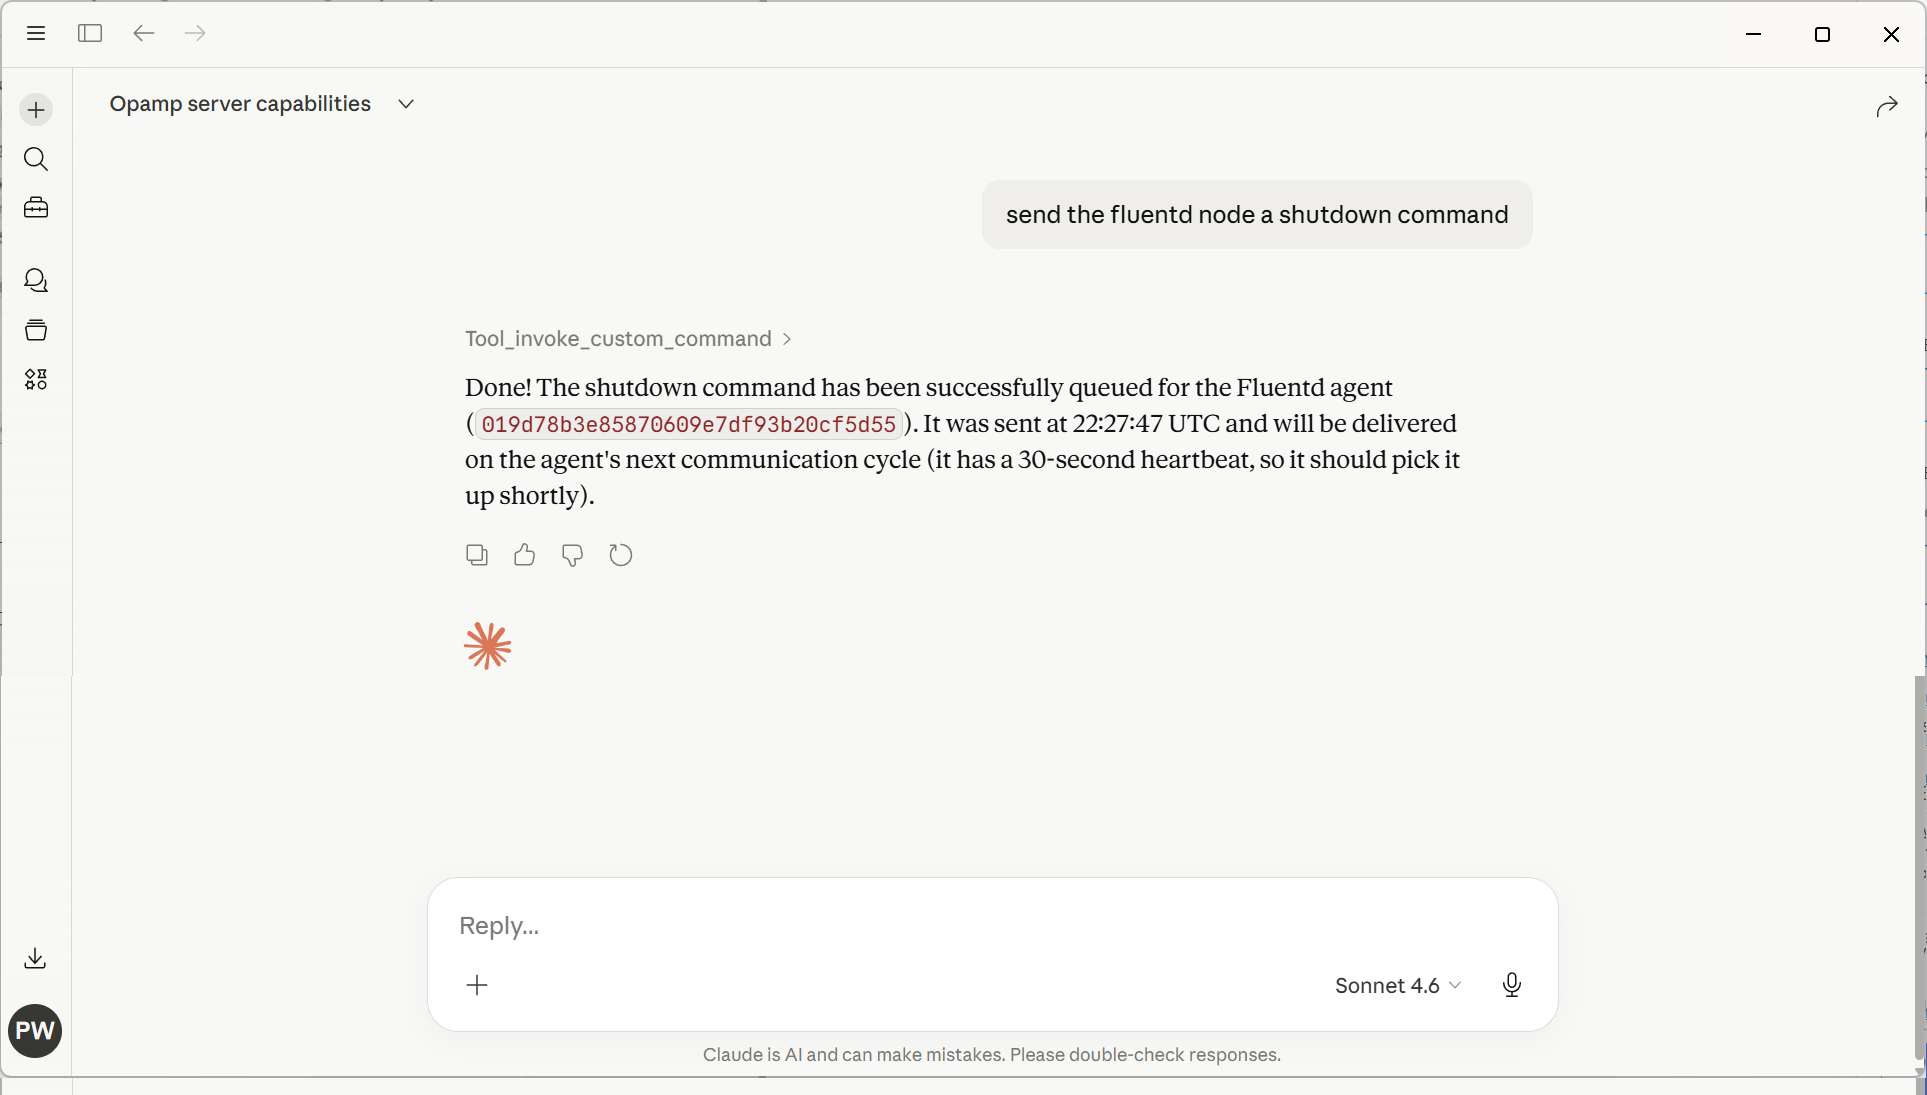
The following screenshot illustrates using plain text rather than trying to come up with structured English to get the OpAMP server to shut down a Fluentd node (in this case, as we only had 1 Fluentd node, it worked out which node to stop).
Interesting considerations
What will be interesting to see is the LLM token consumption changes as the portfolio of managed agents changes, given that, to achieve the shutdown, the LLM will have had to obtain all the Fluent Bit & Fluentd instances being managed. If we provide an endpoint to find an agent instance, would the LLM reason to use that rather than trawl all the information?
Next phase
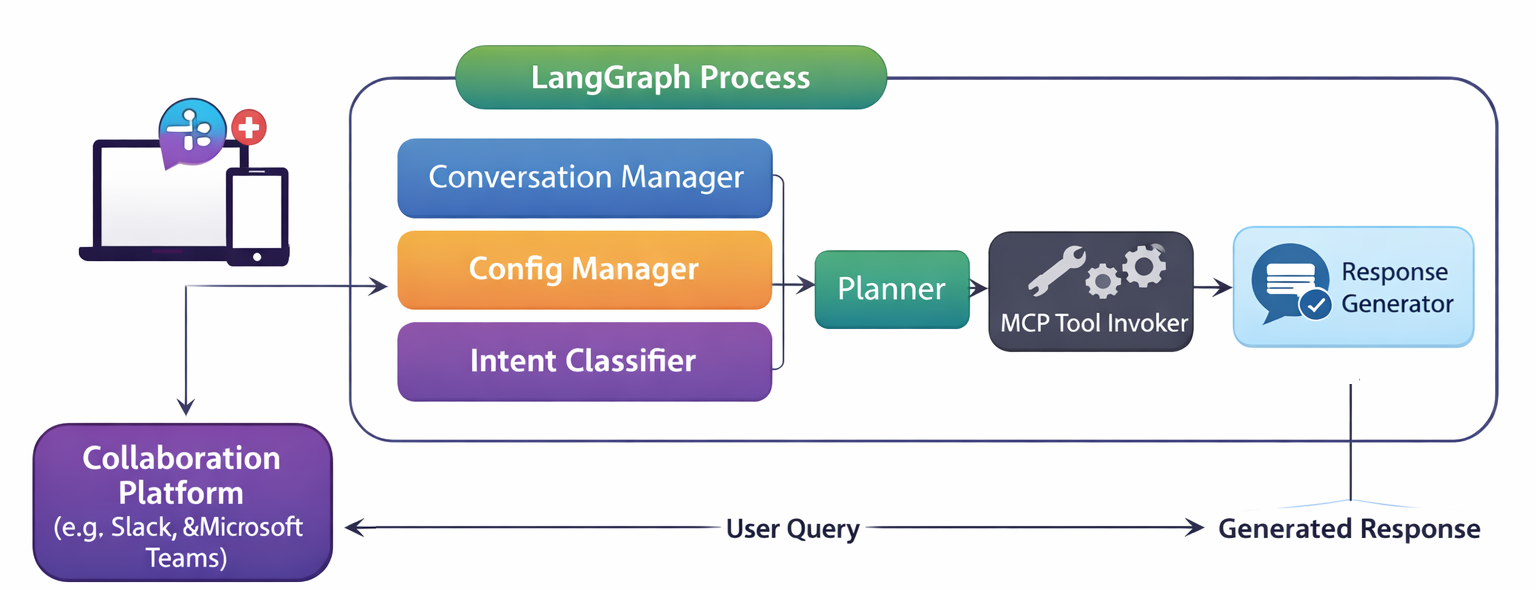
ChatGPT, Claude Desktop, and others already incorporate some level of collaboration capabilities if the users involved are on a suitable premium account (Team/Enterprise). It would be good to enable greater freedom and potentially lower costs by enabling the capability to operate through collaboration platforms such as Teams and Slack. This means the next steps need to look something along the lines of:
There has been a rapidly growing series of articles being written about the limited launch of Mythos, a new LLM. The evolution of models has helped quickly advance AI-assisted software development. But the capabilities of Mythos and Project Glasswing that really grabbed attention and concern.
Glasswing is an initiative that allows major partner software and service vendors to access the Mythos model. This is because Mythos has made significant advances in identifying software vulnerabilities and generating exploits for them. This has been illustrated by Anthropic’s Red team – which found bugs in OpenBSD (OS) that have evaded detection for as much as 27 years. While the BSD family of operating systems isn’t as pervasive as Linux, they both share a similar open ethos and a sufficient community to keep them active and maintained. The underlying message here is that we can find and exploit such vulnerabilities, and there are certainly opportunities to do so elsewhere, in software that can affect a great many more users, such as Firefox.
Having key software vendors, such as OS and browser vendors, get access is certainly a positive step, but it doesn’t address a key consideration. Applying code fixes and releasing updates does not, by itself, equate to being safer. The true challenge is for end users and organisations to recognise the need to roll out updates quickly. This is where the source of true concern should be. The concerns …
Organisations don’t always release patches as soon as they’re available. There is an element of testing to ensure no adverse impact on each organisation’s setup. Even with simple browser changes, something affects the app’s behaviour.
Change represents risk, and organisations that experience issues during rollouts become increasingly risk-averse. Ironically, this is counterintuitive, but a very human reaction.
Vendors’ patching tends to prioritise the latest versions of products, which can create dependency challenges. Bringing software up to date can result in a growing infrastructure footprint (more storage, memory and CPU needed – vendors add capabilities and features to compete and meet customer feature needs, driving continuous growth). That can really add costs, particularly in highly distributed use cases, such as user desktops and IoT devices. Addressing the accumulation of patches means devices no longer have the capability to properly service the new footprint. Consider this: why do people replace smartphones? Sometimes it’s hardware features like a better camera, but often it’s simply not enough storage or not being able to run all the apps, photos, etc.
.Digging into some of the details from the Red Team shows that the LLM usage costs to uncover the vulnerabilities run from $50 – $20,000. This could have ramifications for smaller, more specialised software solutions where the cost of regularly rerunning the analysis outstrips potential revenue. As a result, we could suddenly see software product prices climb, or companies simply stop producing products we depend on. This may also see bad actors wanting to more quickly recoup the cost by accelerating the use of new exploits, in other words, more attacks, coming more quickly. Such considerations will create more pressure on the speed of patch cycles.
This level of capability suggests that we really do need to ensure people shift from boundary-style security to security at every layer of our solutions. That’s not just simply authentication, but code being defensive, validating data values it gets given and os on.
All of this means we have to change mindsets from just enough, or simply putting a front-line security layer in place, to embedding. As end users, we must start to adopt several behaviours:
Security conscious with our own devices – keeping software up to date and patched. I would consider my family to be above average when it comes to tech savvy, but even I am having to go in and run Windows updates on laptops, for example.
Start voting with our feet – many of the services we use are largely or entirely software-powered (banks, energy providers), if those providers show signs of not taking security seriously enough, time to go elsewhere before we become victims.
Keeping up
One observation that the Mythos and Project Glasswing reporting is that the advancements are significant step changes, not incremental advancements (for example, Antghropic’s Sonnet 4.6 was only released a couple of months ago, and didn’t score highly for creating exploits – although better at detection). This suggests a couple of things …
IT law has always played a game of catch-up, but if the advancements are going to be this large and this frequent, we have to start legislating against hypotheticals and allowing legal precedents to produce fine detail interpretations.
We may have to consider big-brother observation of AI use, mitigated by strong transparency rules governing the handling of findings.
Is the idea that we need to start looking at incorporating something like Asimov’s 3 Laws of Robotics into LLMs now looking far-fetched?
Do we need to start thinking about mitigating the risk of deep exploits by bringing back the possibility that systems must be air-gapped?
Hyperbole?
It would be easy to put this down to hyperbole, or wanting to be a click-baity, but this is gaining a lot of high-profile attention, just consider these examples:
The software industry’s current upheavals due to AI are showing signs of unexpected and unintended victims, one of which is open-source software. Open-source foundations run very deep, from Linux to web and app servers, and even to key cryptography technologies.
While there are commercially funded open source efforts, such as chunks of Kubernetes, depending upon which reports you look at, 10-30% of the effort comes from individuals providing their own personal time for free. But we’re seeing a number of threats growing on this…
The number of maintainers is small on some projects. A really good example of this is the Nginx Ingress controller for Kubernetes, which is now no longer being maintained, not because it isn’t needed, but because no one was willing to step up to the plate with their own time or provide salaried engineers. This has triggered something of an outcry (see here, for example).
As this article Microsoft execs warn agentic AI is hollowing out the junior developer pipeline shows, AI-assisted development risks harming the flow of development skills. The issue is that if all junior engineers primarily rely on AI to code and test functionality, the hard-earned experience that teaches you what is good, bad, and where the pitfalls are, they will not gain. Meaning, the skills needed to understand and maintain very large codebases won’t be as strong.
GitHub has argued (here) that AI in development has made it easier for people to get involved and contribute to open-source initiatives, and I’d agree it makers it easier. The challenge, I think, is less an issue of ease than of mindset. I would argue that it is the motivation to contribute and the satisfaction of having contributed that drives open-source contributions, but this is at risk of being undermined (papers such as On Developers’ Personality in Large-scale Distributed Projects indicate open-source contributors tend towards a personality profile, which maybe more suspectable to issues that can lead them to disengage (Connection Between Burnout and Personality Types in Software Developers). While not concrete, overload OSS contributors, and they’re more likely to disengage from contributing.
AI slop, as a result of using a poor coding model, or poor prompting, is showing us that, unwittingly (or through deliberate maliciousness we are seeing pull requests that are buggy, or junk being created at ever faster rates. This puts more work on the core developers to just manage PRs, as described in AI is burning out the people who keep open source alive (another such article at CNCF – Sustaining open source in the age of generative AI). Not to mention even worse actions, such as that described in An AI Agent Published a Hit Piece on Me. This sort of thing will affect people’s willingness to be involved, even when their time is being paid for by a company. This concern is such that InfoWorld reported GitHub are considering the ability to restrict PR velocity (see here).
Another side effect, with the ‘AI arms war’, increases pressure within organisations to adapt, or accelerate as a result of AI expectations. Those donating personal time are less likely to find time to support open-source initiatives, as their focus will be very much on staying secure in their day jobs.
There is no single or simple solution. But that doesn’t mean there aren’t things we can do to help. Some immediate possibilities include:
better messaging about what makes up and propels open-source initiatives beyond commercial contributions. This can help counter the perception that organisations like the CNCF appear to be leaning into large commercial organisations and following open-source business models. But that isn’t the case, and even in the commercial setup, the teams aren’t necessarily that large.
I’m not an advocate of the dual licensing model, as it can create uncertainty in user communities and potential adopters of technologies. This uncertainty can drive disruptive changes; we’ve seen this with OpenSearch and ElasticSearch, OpenELA fork of Linux, among others. It can also hamper early-stage startups. But we can do something: a low-cost entry into CNCF that can help finance the not-for-profit development setups. Use the PR process to help collect metrics and recognise organisations that contribute even a little through PRs, biasing that recognition toward projects with limited support. Not to mention recognising contributors and committers individually (just as CNCF and Linux Foundation provide recognition to conference speakers).
Companies employing early years engineers should implement initiatives that require some development work to be performed without AI assistance and use performance tooling. Yes, this means a short-term drop in productivity, but one thing my years in the industry and training have taught me is that understanding how things work under the hood makes it easier to address problems and recognise ‘bad smells’. Understanding this, helps understand how solutions can scale.
Perhaps University courses could consider awarding credits to students who support important open-source projects, or allow a level of contribution to count toward coursework. This sort of thing would also open up the open-source world a lot more. I, for one, would give credit to a graduate who has contributed to a reputable open-source initiative.
There is on thing I am certain of, though, it is the leadership and sponsors of organisations such as CNCF, Linux Foundation, Apache, Open Source Initiative that can influence the situation the most, and it is in everyone’s interest that when open-source components have to be folded that there is atleast an easier off-ramp, than the 6 months given to switch from using something like NGINX Ingress Controller.


You must be logged in to post a comment.