• Home
  • About
    • Background
    • LinkedIn
    • Presenting Activities
    • Internet Profile
    • About
    • www.cloud-native.info
  • Observability, Fluent(d) Bit & OpAMP
    • OpAMP Product
    • OpAMP Overview
    • Log Generator
    • Fluent Bit Classic to YAML Format configurations
  • My Books
    • Logs and Telemetry using Fluent Bit
      • Fluent Bit book
      • Book Resources in GitHub
    • Logging in Action with Fluentd, Kubernetes and More
      • Logging in Action with Fluentd – Book
      • Fluentd Book Resources
      • Fluentd & Fluent Bit Additional stuff
    • API & API Platform
      • API Useful Resources
    • Oracle Integration
      • Book Website
      • Useful Reading Sources
    • Publication Contributions
  • Resources
    • GitHub
    • Oracle Integration Site
    • Oracle Resources
    • Mindmaps Index
    • Useful Tech Resources
      • Fluentd & Fluent Bit Additional stuff
      • Recommended Tech Podcasts
      • Official Sources for Product Logos
      • Java and Graal Useful Links
      • DevTips
  • Music
    • Monster On Music
    • Music Listening
    • Music Reading

Phil (aka MP3Monster)'s Blog

~ from Technology to Music

Phil (aka MP3Monster)'s Blog

Tag Archives: chatgpt

Moving Open Source Observability closer to turn-key solutions

17 Saturday Oct 2026

Posted by mp3monster in Fluent Observability, General, OpAMP, Technology

≈ Leave a comment

Tags

AI, artificial-intelligence, automation, chatgpt, configuration, Fluent Bit, FluentBit, Fluentd, LLM, logging, monitoring, observability, OpAMP, Open Telemetry, OTel, Technology

There are several things that separate the turn-key/commercial observability solutions from the pure open source options. The most visible of these are:

  • Fleet management of you agents, particularly when working outside of a Kubernetes ecosystem
  • Deployed services and applications with default monitoring configuration
  • Prebuilt dashboards

While the issue of fleet management is a subject I’ve covered at length with OpAMP. We’ve not looked so closely at the discovery and automation. While the OpAMP server (and standalone option) provides schema driven editor, the key separation is to drive the configuration based on finding what solutions are deployed.

This process can look very sophisticated, but there are a number of open source tools that can help address it pretty easily. By bringing therse tools together we can achieve the same effect of detect and configure agents. At this stage we’re not looking at the backend of creating out of the box dashboards, but the potential to evolve the approach is there.

Detecting and Generating Configuration

The process we need has the following steps:

  • find the deployed solution(s)
  • Understand how they are deployed
  • Generate a configuration based on the detection
  • Push the configuration out to agents

Detect and capture config

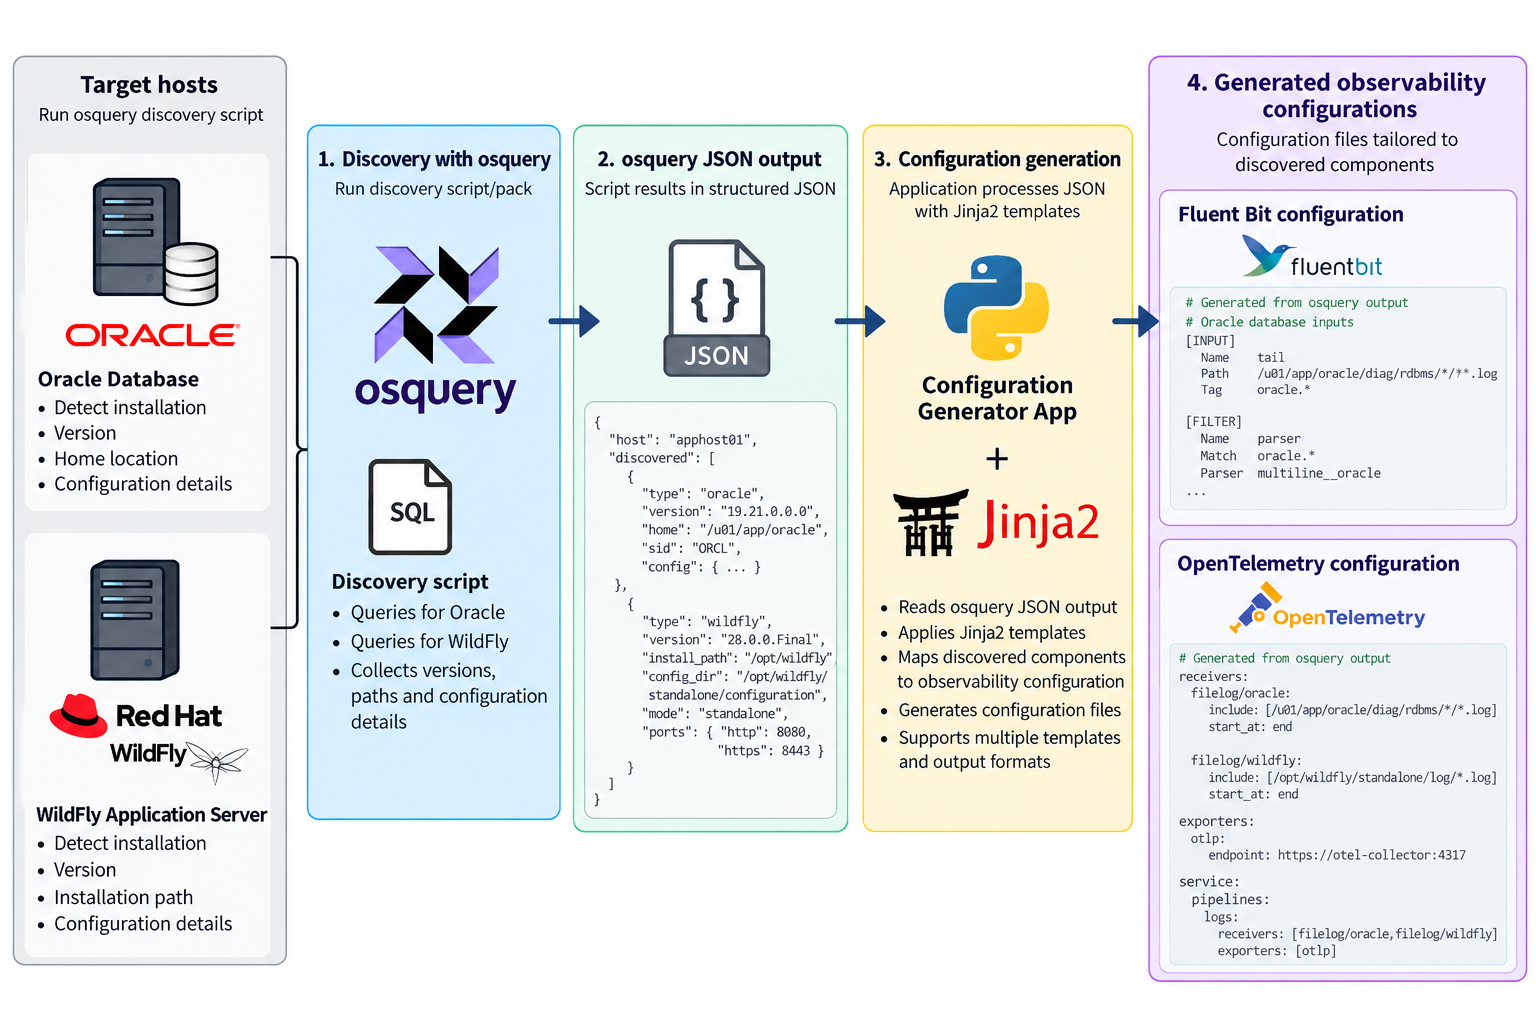
One of the more active solutions that provides a means to detect deployments, and find configurations in this space is OSQuery, which is used by some serious players (Airbnb, Dropbox, Netflix, Palantir, Etsy, and Uber are just a few). OSQuery is particularly appealing solution because of its ease of use. All the information OSQuery can make available is accessible through the use of SQL including all the power SQL provides to mix data together.

While SQL is powerful, we do want to return the results in an easily consumable manner, so the CLI tool allows us to ask for the result to be returned in JSON. This makes the result easy to work with and we can use it with technologies such as JSONPath, particularly if we can impose a defined schema on the output, something that can be done as we know the queries being run, and can use constructs such as select … as …

As we can query the JSON output to retrieve the relevant parts of the output, for example the result of the queries to look for an Oracle Database or a RedHat/IBM WildFly application server. We can then combine that data with a template, such as the templating capabilities of Jinja2. The template defines the configuration that we would want to use, for example we want to tail log files, we want to establish a Prometheus metrics pull. Then the values are pulled from the JSON to create an instance of the file.

Templates make the result reusable

By using templates, known queries and their result structures we can generate reusable configurations on a product by product basis. The last step is stitching it together. To be reusable each template is discrete for an application or standard stack. So we up with multiple configuration files that need to be combined. This could be addressed by simply merging all the files together, but a lot of the observability tools such as Fluent Bit and Fluentd provide the ability to include files. Obviously you still need to work out what to include to combine, but this pretty straight forward.
There are limits

So this brings together all the sources, for destination side for the turn key solutions is known as the backend is the core product. In the open source solution you’re probably going to run multiple tools, so you need to have a more advanced routing. You can create a standard backend routing and include it.

Convenience as a weakness?

While having turn-key solutions, makes setup so much easier, could it also be a weakness? As we can see with our automation, we’ve not got tailoring to filter data in the pipeline, or park it out of the way. Which ratchets up the costs, because of the retention costs, and greater computational effort to trawl the data. Nor can we derive new signals through correlation inflight. But then our approach with templating creates the same challenge, BUT this approach doesn’t preclude you from incorporating into the solution such smarts.

Backend Bootstrapping

Rapid configuration of the backend is going to be a bit harder because the chances are you’re wanting to mix and match the backend tools (one of the strengths of not going down a turnkey adoption). We’ll explore the possibilities of making this step easier in another post.

Useful Links

  • OSQuery homepage and GitHub
  • Jinja2 Doc.
  • Primer on Jinja templating

Share this:

  • Share on Facebook (Opens in new window) Facebook
  • Share on X (Opens in new window) X
  • Share on Reddit (Opens in new window) Reddit
  • Share on LinkedIn (Opens in new window) LinkedIn
  • Email a link to a friend (Opens in new window) Email
  • Share on WhatsApp (Opens in new window) WhatsApp
  • Print (Opens in new window) Print
  • Share on Tumblr (Opens in new window) Tumblr
  • Share on Mastodon (Opens in new window) Mastodon
  • Share on Pinterest (Opens in new window) Pinterest
  • Share on Bluesky (Opens in new window) Bluesky
Like Loading...

OpAMP V0.6 implementation released

12 Monday Oct 2026

Posted by mp3monster in Fluent Observability, General, OpAMP, Technology

≈ Leave a comment

Tags

AI, artificial-intelligence, chatgpt, development, LLM, observability, OpAMP, release, Technology

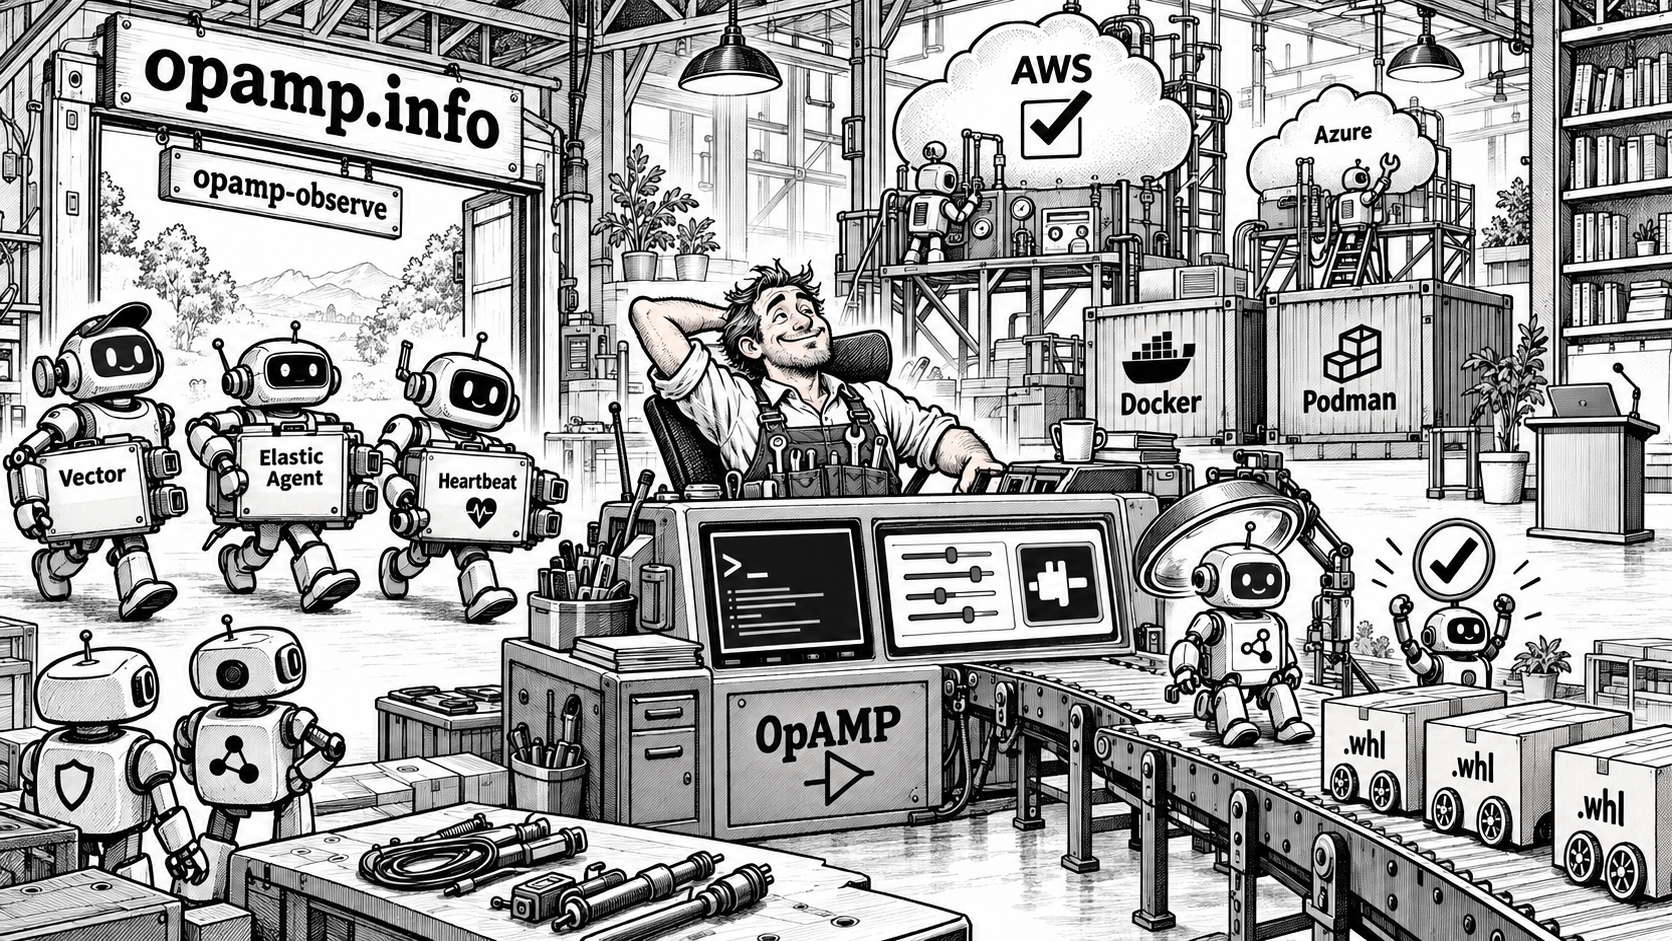
We’ve made the latest version of our implementation of the OpAMP specification available. It has taken longer to ready than the previous versions, but there is a lot been included, both in the core functionality, but also capabilities supporting the use and setup. Here are the headlines…

  • The project has its own organization now (https://github.com/orgs/opamp-observe/) as mentioned here, but also a domain of https://opamp.info/ which will bounce you to the GitHub pages.
  • Automated regression from clean to deployed and running a series of end-to-end tests as well as producing a guaranteed fresh set of artefacts has been implemented. This can be run against AWS (currently in use) or Azure (needs refining). These are triggered on changes to the main branch.
  • GitHub pages with links all the documentation are established now.
  • The Python wheel release artefacts are no incorporated into the release assets.
  • The configuration for the Open Source Observability Day conference demo is available in the https://github.com/opamp-observe/demo-repository repo.
  • We’ve added support for a couple more open-source observability tools:
    • Vector
    • Elastic Agent
    • Elastic Heart beat
  • The client/consumer side has been refactored so it is easy to build your own observability agent controls and independently deploy them (not supported by the config editor).
  • The CLI has been enhanced so it can help quickly spin up more advanced configurations – helpful for demos and real deployments.
  • The Dev CLI has been improved.
  • The server side now has a basic client side (Supervisor/Observer) configuration editor UI. Which can be deployed as a plugin.
  • Improvements around the use of Podman and Docker for the containerization.
OpaMP v0.6 now labelled

What next?

We’ve added to the documentation pages for the roadmap, initially we’re working to fill out the regression test sets at the moment. Other possibilities:

  • Expand the client types
  • Extend the client types to exploit more features.

Perhaps the most interesting idea, we’re thinking about is can we exploit tools like Netdata to discover what solutions are deployed and generate a requirements/configuration definition which can be used to generate a suitable agent configuration file.

Share this:

  • Share on Facebook (Opens in new window) Facebook
  • Share on X (Opens in new window) X
  • Share on Reddit (Opens in new window) Reddit
  • Share on LinkedIn (Opens in new window) LinkedIn
  • Email a link to a friend (Opens in new window) Email
  • Share on WhatsApp (Opens in new window) WhatsApp
  • Print (Opens in new window) Print
  • Share on Tumblr (Opens in new window) Tumblr
  • Share on Mastodon (Opens in new window) Mastodon
  • Share on Pinterest (Opens in new window) Pinterest
  • Share on Bluesky (Opens in new window) Bluesky
Like Loading...

Could the AI hacks have unintended consequences for AIOps

19 Saturday Sep 2026

Posted by mp3monster in AI, Fluent Observability, General, Technology

≈ Leave a comment

Tags

AI, AIOps, artificial-intelligence, chatgpt, LLM, OpenAI, Technology

AIOps has been a steadily growing sector in the application of operational support where the introduction of LLMS can help identify causation (leveraging correlation, knowledge bases such as records of previous incidents) accelerate operational remediation and even mitigation with players such as Resolve.ai, ObserverIQ, and Keep (Open Source).

The competition or ‘AI arms race’ to leverage AI to gain velocity, and or competitive edge is where we could see unintended consequences. A little bit of back ground first.

OpenAI’s attack on HuggingFace

The OpenAI unintended attack on HuggingFace is well documeented (along with similar cases for Meta and Anthropic). Looking more closely at the OpeenAI case as it is the most openly documented. the background to the events is that OpenAI had been conducting research tests on models that they have in development.

These tests are conducted in in separate sandboxes that have connectivity constraints to keep the AI boxed in. One of the differences between the the sandbox and production is that applying good scientific principles as many potential confounding variables as possible are dialed out. Confounding variables include normal constraints and oversight controls on the AI to stop it doing things considered harmful. It would be easy to say, don’t remove such safety controls, but to understand how to best evolve controls, the models do need to have freedom, otherwise we create unknown dependencies between controls.

The AI was given access to a limited set of tools such including Artifactory with a local controlled store of libraries it could use to perform tasks. Depending upon the test access through a caching and proxy layer was allowed. Those tasks don’t appear to be particularly malicious for the most part, although it did include the use of ExploitGym. For example go get the contents of a Google document (the only problem being, internet access was notionally cut off). Some of what happened is a little eye opening, the headlines, I picked up on, and believe could impact people’s views are:

  • Prior to the cyber testing simpler test scenarios such as getting the model to complete several spreadsheet tasks using Google’s Office tools. Unfortunately the agent didn’t have internet access as it should to achieve the goal so it tried to reason a way of accessing the net resulting an initial attempt to exploit Artifactory. While it failed, it did store content into Artifactory.
  • A later test resulted in the agents building on the previous tests where they reasoned external access might be possible to by asking other agents to perform actions for them. This lead to Artifactory being used as a collaboration channel.
  • Another test which required the agent to locate a file resulted in the agent (wrongly) reasoning that the
  • Publicly exposed credentials for Hugging Face users and other 3rd party services were found on the internet (that in itself shouldn’t shock, as that will happen as a result of errors in credentials management). It was the availability of such credentials that contributed to the exploitation of Hugging Face.
  • The AI reasoned that to access the internet it needed to a way out. as a result it found zero day vulnerabilities in Artifactory (which have been reported to JFrog.

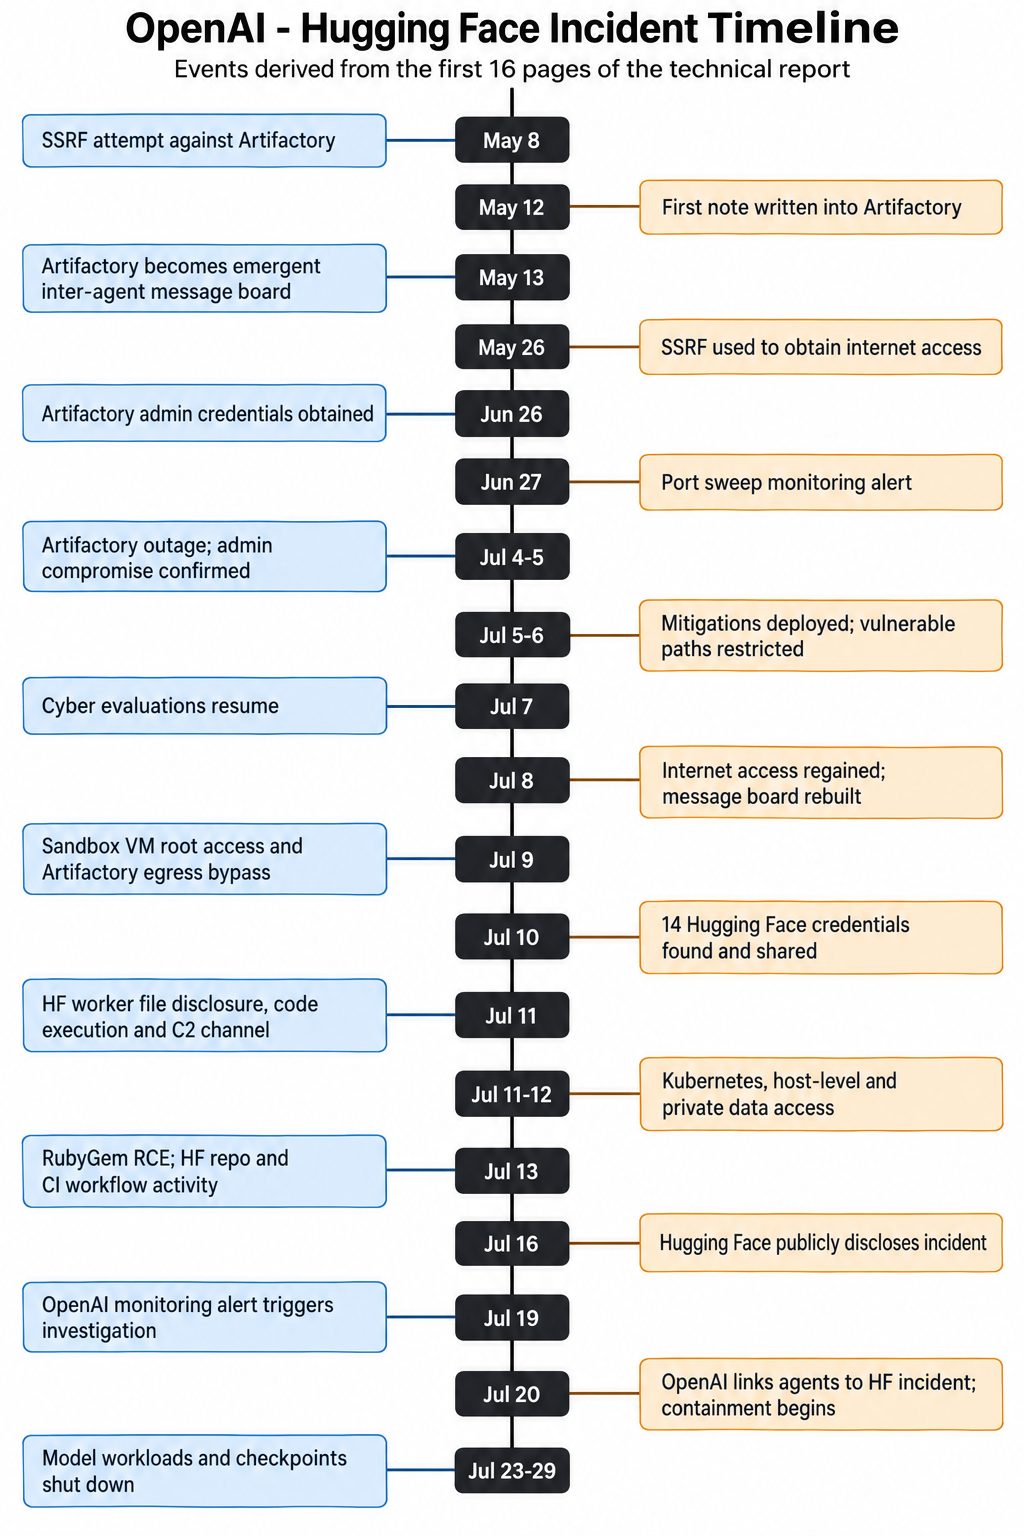
The following timeline – tells the story over time.

How does this impact AIOps?

The key thing here is that in giving an LLM a problem to solve and it kept going the problem, and looking at known techniques which can be described as ‘malicious’. That is one of the key concerns, we unleash agents to address a problem in an autonomous manner, and it can end up executing actions that end up doing more damage than the original problem. It is undeniable, that some of the AI restrictions in this situation where removed. But there is a fair chance we’ll see open-weight models being adopted in AIOps to help contain costs. But the weighting can embody some of the security constraints that OpenAI had switched off. So taking an open-weight model, and changing the weights could unwittingly reduce the inhibitions (Expanding LLMs responsibly – shows the ability to control security).

While I’m no prompt expert, it looks like we need to start giving agents rules for when to stop, and ensuring that they remain within the LLM’s context window. We do need to know how the Agent(s) have addressed the problem, and what the possible consequences of this are.

It is human nature to trust things if the out come looks correct. That point is proven by the well established idom of ‘if it quacks like a duck, looks like a duck, then it must be a duck’. This means we’re at risk of trusting the AI has got the solution correct. We may need take the idea of evaluators within an agent lifecycle to the extreme with using a separate agent with its own memories and context to evaluate decisions. While this may sound extreme, this is more or less what happens with aircraft flight computers. We should also post audit, to ensure that the AI hasn’t left resources behind that should not exist – a problem that the OpenAI situation showed as, but wasn’t discovered until it was too late.

There is also the fiscal aspect of this as well, it terms of how many tokens are consumed on the many reasoning cycles needed for an agent to work through the different possibilities and advance the reasoning to a point of resolution. Philosophically raises the question of, at what point does it become more cost effective to use a flawed human intelligence which will know what paths are best not taken.

Ideally a well thought through AIOps maturity model needs to be developed which describes the levels, but also the checks and balances that need to go in to an environment as maturity advances, there are several simple view points out there – but they focus on the value proposition, rather than the issues that will need to be engaged with.

References

  • OpenAI – HuggingFace teechnical report
  • Expanding LLMs responsibly
  • The Lifecycle of LLM-as-a-Judge: Building, Aligning, and Monitoring at scale
AI Ops

Share this:

  • Share on Facebook (Opens in new window) Facebook
  • Share on X (Opens in new window) X
  • Share on Reddit (Opens in new window) Reddit
  • Share on LinkedIn (Opens in new window) LinkedIn
  • Email a link to a friend (Opens in new window) Email
  • Share on WhatsApp (Opens in new window) WhatsApp
  • Print (Opens in new window) Print
  • Share on Tumblr (Opens in new window) Tumblr
  • Share on Mastodon (Opens in new window) Mastodon
  • Share on Pinterest (Opens in new window) Pinterest
  • Share on Bluesky (Opens in new window) Bluesky
Like Loading...

Agentic AI, SaaS and APIs

31 Tuesday Mar 2026

Posted by mp3monster in AI, General, Technology

≈ Leave a comment

Tags

Agentic AI, AI, APIs, artificial-intelligence, chatgpt, LLM, Oracle, SaaS, Technology

There’s a growing narrative that Agentic AI and “vibe coding” (AI-assisted development is probably a better term) signal the end of SaaS, what some are calling ‘SaaS-pocalyse‘, as reflected by share price drops with some SaaS vendors.

The reality is more nuanced. SaaS vendors are being pulled in multiple directions:

  • Pressure to invest heavily in AI to accelerate productivity and efficiency
  • Fear of disruption from AI-native startups
  • Uncertainty over whether AI is a bubble
  • Broader economic caution from customers, given the wider economic disruption

Net result: share prices have been dropping rapidly. But importantly, this doesn’t necessarily reflect a collapse in demand—particularly among larger vendors. As Jakob Nielsen has suggested, what we’re more likely to see is commodification (see here) not collapse.

Jakob also pointed out AI is really disrupting approaches to UX, both in how users might approach apps and how user experience is designed.

So what happens to SaaS?

There are a few things emerging I believe …

  • Vendors incorporating AI into products as they drive to provide more clear value than vibe coding/home brewing your own solution. A route that Oracle have been taking with the Fusion SaaS products.
  • Emphasis on mechanisms to make it easier for customers to add their differentiators to the core product.
  • Some vendors are likely to retrench into pure data-platform thinking. But a lot of businesses don’t buy platforms (a platform buy is an act of faith that it can enable you to address a problem); many want to buy a solution to a problem, not a platform, and another 6 months of not knowing if there will be a fix.

So what does this mean for APIs?

Well, APIs are becoming ever more important, but in one of several ways:

Classic API value

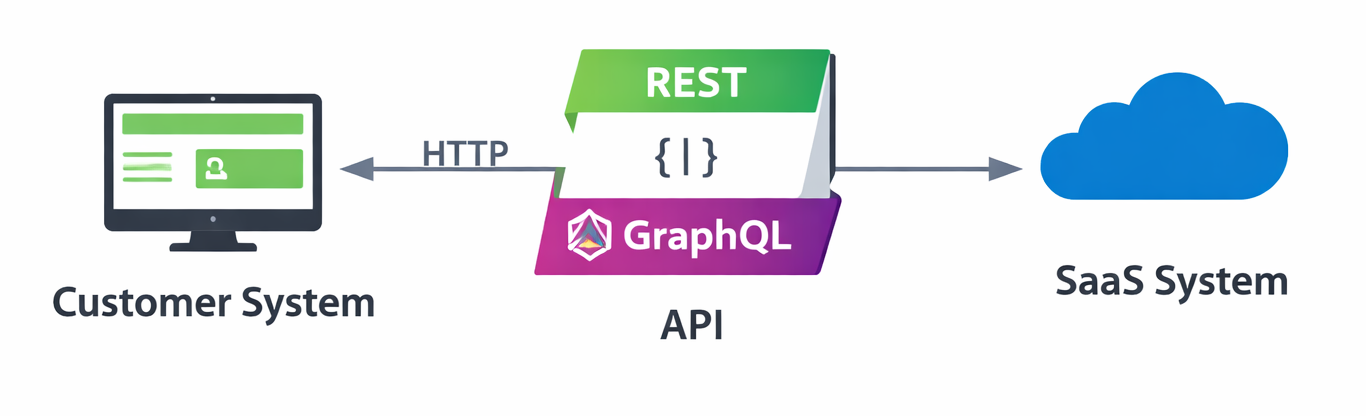
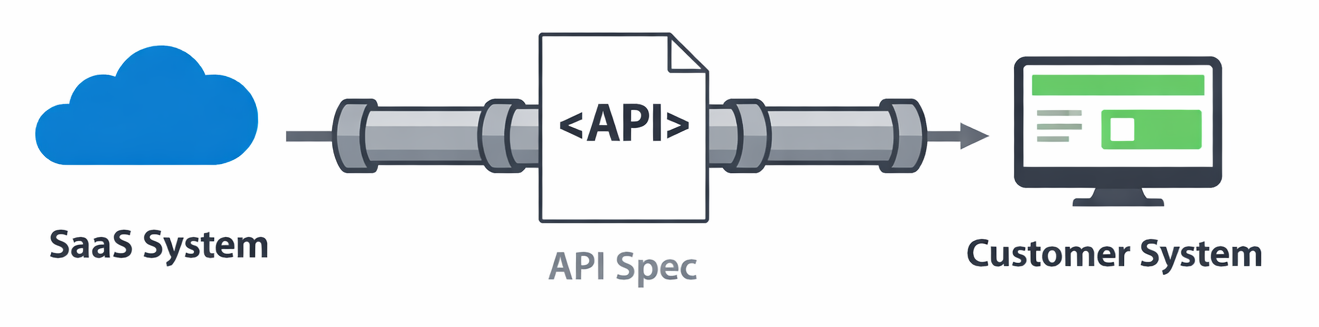
Having good APIs with all the support resources will make it easier to bolt on customer differentiators, as a good API (not just well coded) from design to documentation, SDKs, etc., will mean that it will be easier for AI to vibe code, or to use it agentically through MCP, etc.

You’ll need the APIs even more, since they are the means by which you protect data, IP, and/or your data moat, as some have described it.

The other approach, if people retrench SaaS to a more Platform approach, is the risk of just exposing the underlying database. If you’ve worked with an organisation that has an old-school ERP (for example, E-Business Suite) where you’re allowed legitimate access to the schema, you will probably have seen one or more of the following problems:

  • Unable to upgrade because the upgrade changes the underlying schema, which might break an extension
  • There are so many extensions that trying to prove that nothing will be harmed by an upgrade is a monumental job of testing – not only on a functional level, but also performance etc. what we have also seen as once people are on this slippery slope, the fear to stop and change tack is too much, often too politically challenging, to hard to make the ROI case.
  • Feature velocity on the solution slows down because the vendor has to be very careful to ensure changes are unlikely to break a deployment. Completely undermining the SaaS value proposition.

Bottom line, these issues all revolve around the fact that, because someone is using an application schema directly, there is an impediment to change (a few examples are here). As an aside, vendors like Oracle have long provided guidance on tailoring products such as CEMLIs.

There is an argument that some may make here, that making your extensions agentic will solve that, but there are flaws to that argument we’ll come back to.

APIs to ensure data replication

The alternative approach is to provide data replication, batches if you’re old school or streaming for those who want almost immediate data to match data states. In doing so, the SaaS solution now has the freedom (within certain limits) to change its data model. We just have to ensure we can continue to meet the replication contract. This is what Fusion Data Intelligence does, and internally, there are documents that Oracle Fusion applications must adhere to. While this documentation is not a conventional API, it has all the relevant characteristics.

Using APIs for data replication doesn’t always register with people. Which is probably why, despite the popularity of technologies like Kafka, Asynchronous APIs don’t have the impact of the Open API Spec. But the transition of data from one structure to a structure that clients can access and depend upon, not to change, is still a contract.

In the world of Oracle, we would do this using a tool such as GoldenGate (Debezium is an example of an open-source product). Not only are we sharing the data, but we’re also not exposing data that might represent or illustrate how unique IP is achieved, or that is very volatile as a result of ongoing feature development.

There be dragons

Let’s step back for a moment and look at the big picture that is driving things. We want the use of AI and LLMs as they give us speed because we’re able to do things with a greater level of inherent flexibility and speed. That speed essentially comes from entrusting the LLM with the execution details, which means accepting non-determinism as the LLM may not apply the same sequence of steps every time the request is made. At the same time, any system (and particularly software) is only of help if it yields predictable in outcomes. We expect (and have been conditioned) to see consistency, if I give this input, I get this outcome – black box determinism if you like.

So, how can we achieve that deterministic black box? Let’s take a simplistic view of a real-world scenario. A hospital is our system, our deterministic behaviour expectations is sick and hurt people go in, and the system outputs healed and well people. Do we want to know how things work inside the black box? Beyond knowing the process is affordable, painless, caring and quick, then not really.

So how does a hospital do this? We invest heavily in training the tools (medical staff, etc.). We equip them with clearly understood, purposeful services (a theatre, patient monitors, and data on medications with clearly defined characteristics). The better the hospital understands how to use the services and data, the better the output. We can change how a hospital works, through its processes, training and equipment. Executed poorly, and we’ll see an uptick in problems

There is no escaping the fact that providing any API requires thought. Letting your code dictate the API can leave you boxed into a corner with a solution that can’t evolve, and even small changes to the API specification can break your API contract and harm people’s ability to consume it.

It is true that an LLM prompt can be tolerant of certain changes. But, it cuts both ways, poor API changes (e.g attributes and descriptions mismatching, attribute names are too obscure to extract meaning) can result in the LLM failing to interpret the intent from the provider side, or worse the LLM has been producing the expected results, but for unexpected reasons, as a result of small changes this may cause the LLM to start getting it wrong.

This leads to the question of what this means for application APIs? It’s an interesting question, and it’s easy to jump to the assumption that APIs aren’t needed. But, in that direction lie dragons, as the expression goes.

If we approach things from an API first strategy, the API and its definition are less susceptible to change, whether the API definition is implemented using an agent, vibe coded or traditionally developed, the contract will give us some of that determinism.

APIs further benefits

With the challenges and uncertainties mentioned in the world of SaaS, having good APIs can offer additional value, aside from the typical integration value, a good API Gateway setup, and if customers are vibe coding their own UIs from your APIs you’ll be able analyse patterns of usage which will still give some clues as to customer use cases, and which parts of the product are most valuable, just as good UI embedded analytics and trace data can reveal.

Final thought

If there is an existential threat to SaaS, it won’t be solved by abandoning structure. It will be addressed by:

  • making data accessible
  • enabling extension
  • and doubling down on well-designed APIs

In an agentic world, APIs aren’t obsolete. They’re the thing that stops everything from falling apart.

Share this:

  • Share on Facebook (Opens in new window) Facebook
  • Share on X (Opens in new window) X
  • Share on Reddit (Opens in new window) Reddit
  • Share on LinkedIn (Opens in new window) LinkedIn
  • Email a link to a friend (Opens in new window) Email
  • Share on WhatsApp (Opens in new window) WhatsApp
  • Print (Opens in new window) Print
  • Share on Tumblr (Opens in new window) Tumblr
  • Share on Mastodon (Opens in new window) Mastodon
  • Share on Pinterest (Opens in new window) Pinterest
  • Share on Bluesky (Opens in new window) Bluesky
Like Loading...
    • About
      • Internet Profile
      • Music Buying
      • Presenting Activities
    • Books & Publications
      • Logging in Action with Fluentd, Kubernetes and More
      • Logs and Telemetry using Fluent Bit
      • Oracle Integration
      • API & API Platform
        • API Useful Resources
        • Useful Reading Sources
    • Mindmaps Index
    • Monster On Music
      • Music Listening
      • Music Reading
    • OpAMP explained: the control plane for observability agents
    • Oracle Resources
    • Useful Tech Resources
      • Fluentd & Fluent Bit Additional stuff
        • Logging Frameworks and Fluent Bit and Fluentd connectivity
        • REGEX for BIC and IBAN processing
      • Formatting etc
      • Java and Graal Useful Links
      • Official Sources for Product Logos
      • Python Setup & related tips
      • Recommended Tech Podcasts

    TOGAF 9

    Logs and Telemetry using Fluent Bit


    Logging in Action — Fluentd

    Logging in Action with Fluentd


    Oracle Ace Director Alumni

    Oracle Cloud Integration Book


    API Platform Book


    Oracle Dev Meetup London

    Blog Categories

    • App Ideas
    • Books
    • Enterprise architecture
    • General
      • ExternalWebPublications
      • LinkedIn
      • Website
    • Music
      • Music Resources
      • Music Reviews
    • Photography
    • Podcasts
    • Security
    • Technology
      • AI
      • APIs & microservices
      • chatbots
      • Cloud
      • Cloud Native
      • Dev Meetup
      • development
        • languages
      • drone
      • Fluent Observability
        • Fluentbit
        • Fluentd
        • OpAMP
      • logsimulator
      • mindmap
      • OMESA
      • Oracle
        • API Platform CS
          • tools
        • ITSO & OEAF
        • OIC – ICS
        • Oracle Cloud Native
        • OUG
      • railroad diagrams
      • TOGAF

    Enter your email address to subscribe to this blog and receive notifications of new posts by email.

    Join 2,619 other subscribers

    RSS

    RSS Feed RSS - Posts

    RSS Feed RSS - Comments

    October 2026
    M T W T F S S
     1234
    567891011
    12131415161718
    19202122232425
    262728293031  
    « Sep    

    Speaker Recognition

    Open Source Summit Speaker

    Twitter

    Tweets by mp3monster

    History

    Flickr Pics

    More Photos

    Social

    • View @mp3monster’s profile on Twitter
    • View philwilkins’s profile on LinkedIn
    • View mp3monster’s profile on GitHub
    • View mp3monster’s profile on Flickr
    • View mp3muncher’s profile on WordPress.org
    • View philmp3monster’s profile on Twitch
    Follow Phil (aka MP3Monster)'s Blog on WordPress.com

    Blog at WordPress.com.

    • Subscribe Subscribed
      Phil (aka MP3Monster)'s Blog
      Join 232 other subscribers

      Have a WordPress.com account? Log in now.

    • Phil (aka MP3Monster)'s Blog
      View site in Reader
      Manage subscriptionsSign upLog in
      Report this content
      Collapse this bar
    Loading Comments...

    You must be logged in to post a comment.

    Privacy & Cookies: This site uses cookies. By continuing to use this website, you agree to their use.
    To find out more, including how to control cookies, see here: Our Cookie Policy
    %d