When I wrote Logging In Action, I found that to help with setting up and testing logging pipelines, having a utility that could just take existing logs and play them so it looked like a real application was generating the logs was helpful – not only for the book, but in everyday work.
The natural evolution was: can I also create and run synthetic logs through observability systems so we can ensure log thresholds, filters, alerts, etc. worked as expected. Not to mention taking synthetic or real logs and applying some basic reformatting so we could mimic Apache or Nginx web servers, for example.
So the LogGenerator (sometimes called Log Simulator) was born and made available. At the time, my development skills were centred on Java (and I loved Groovy for its convenience and development speed). So we built the solution using Groovy and Java -the net result is that you could create a deployable JAR or run it without the need to first establish a Maven pipeline (without sacrificing the ability to keep polymorphism and abstract layers).
The LogGenerator has had a number of enhancements, so we could use it to check not only tools like Fluentd and Fluent Bit, but also cloud observability tooling such as OCI. This was made to be a pluggable framework so you could add custom targets easily.
Time moves on …
Python continues to grow in popularity and is the default language bundled with Linux. I’m comfortable developing in Python now, and we have the tools I enjoyed with Groovy and Java (no need to mess with build pipelines for quick changes, but it can also be packaged and easily deployed for mainstream adoption).
But it isn’t programming language evolution that has triggered change. OpenTelemetry standards and the golden signals of Logs, Traces and Metrics are the norm. So applying the same principles to the Traces and metrics that the LogGenerator used for logs is a natural evolution.
Deployment
It was pointed out to me that, even if people don’t take the full OpAMP solution we built, the simulator component may be attractive in its own right. This got us to thinking about whether there was value in pairing the SignalGenerator with the OpAMP simulator.
As a result, we created an optional feature that lets us deploy SignalGenerator as an extension of the OpAMP simulator. This gives us multiple deployment options.
A free-standing solution in its own right, with no need for anything else. Ideal for dropping into test environments to exercise your Observability configuration and tuning without needing start-up applications that require large deployments with complex inputs to generate unhappy path signals.
Deploy in a supervised manner using OpAMP – ideal if you want to drive synthetic Observability exercises in a distributed manner.
Plug into the OpAMP simulator – fewer processes running, easier to create custom commands through the OpAMP framework to get the generator to do things from pushing out new data sources to be replayed, to having signal generators simulate Observability data that reflects a distributed cascading failure as means to evaluate smarter AI-driven processes that should be looking for correlations and cause and effect.
The last part with custom messaging over OpAMP is not yet in place, but it’s a candidate for enhancement.
New home
As the Logging in Action book uses the LogGenerator, we didn’t want to make this level of change in the current repository. So we have a new repository within the OpAMP-Observe GitHub organization which has feature parity, but also has a mechanism for simulating metrics (pushing, or allowing the data to be scraped).
The documentation to link the repositories and the GitHub documentation together is a little bit behind, and we need to figure out how to create a manageable playback structure for Traces before we enable that feature.
Another aspect of OpenTelemetry’s OpAMP protocol is the ability to share connections details, not just between the server side of the OpAMP protocol, but with other connections a collector like Fluent Bit could be using such as an OTel consumer for logs, traces and metrics that are being collected that could be a managed Grafana service or another Fluent Bit if you’re using a concentrator network.
This is includes Observability data generated by the collector I.e. Fluent Bit in our case.
Yes, but Fluent Bit doesn’t push its own OTel signals
It is true that out of the box Fluent Bit doesn’t push OTel signals for itself. But this is easily fixed. We can control logging, and metrics that are exposed (and today no traces are produced). The solution is simple, we use Fluent Bit itself to collect the logs and metrics and route them to using an OTel output plugin.
While creating a configuration for sharing seems onerous, once you’ve done it once, you can simply include the config file in every deployment. Further more, if you backend for any of the signals is not Fluent Bit conversant, just use a different Fluent Bit plugin.
Config walkthrough
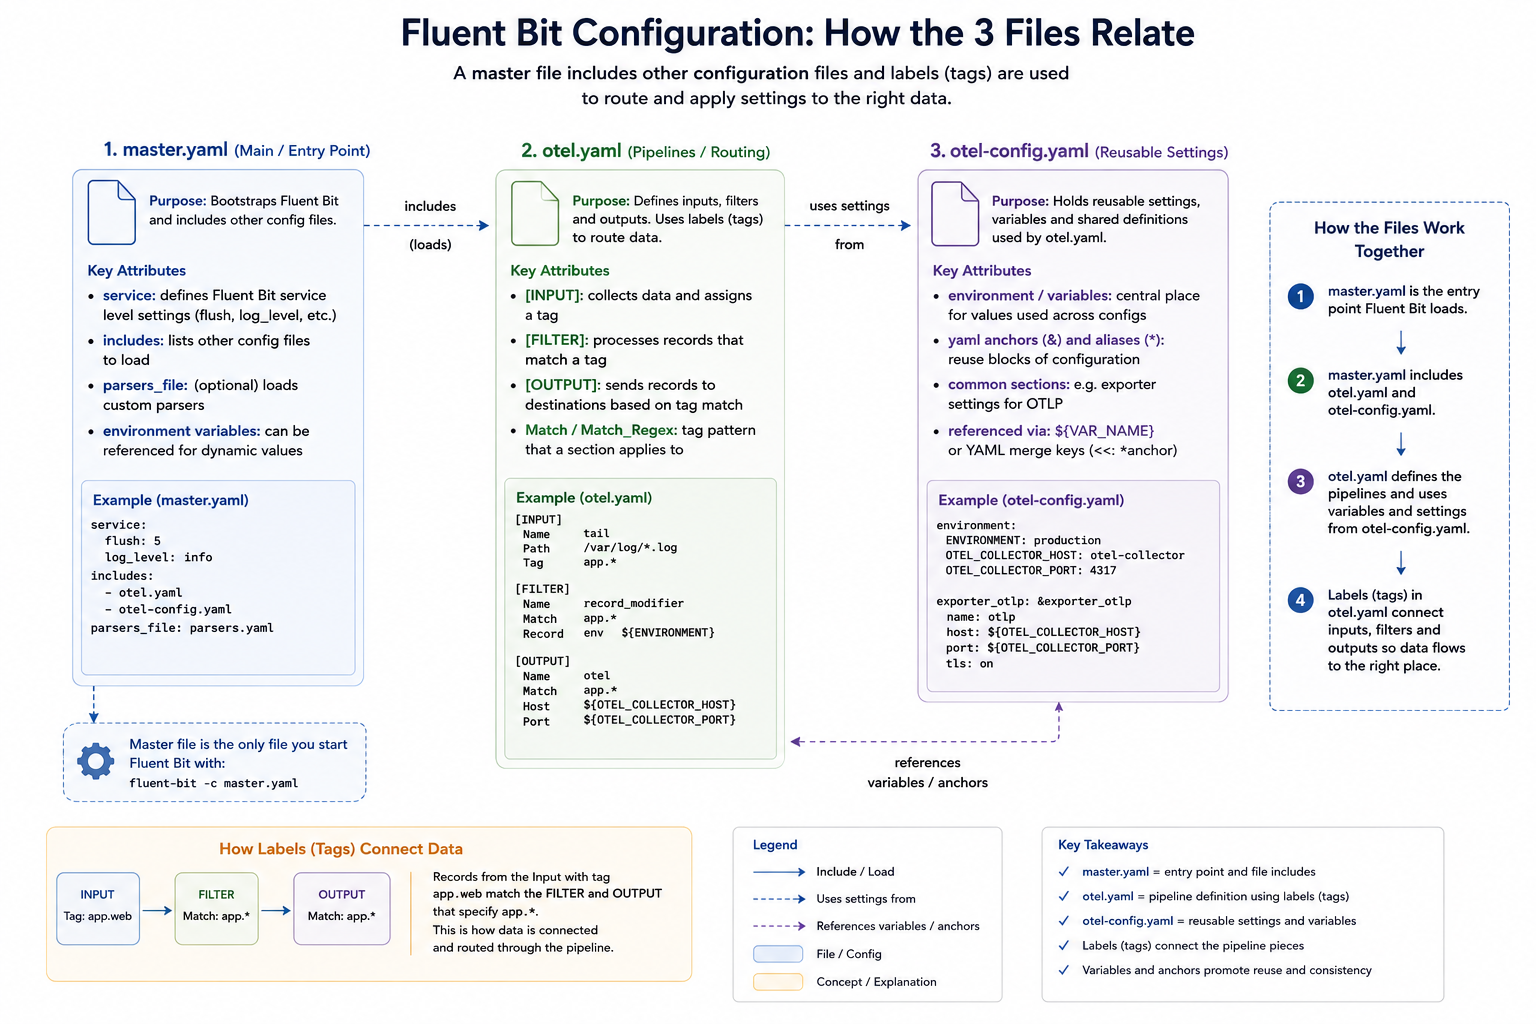
Our configuration consists of several files, which we’ll explain. We’ve adopted a multi-file setup, which works through the use of Fluent Bit’s includes capability so we can separate out the application-level observability configuration (master.yaml), the configuration to allow us to observe Fluent Bit itself (otel.yaml), and the configuration for the connection parameters (otel-config.yaml).
Master.yaml
The master.yaml contains our application observability settings and is the configuration file we pass to Fluent Bit. In this case, we’re simply using a dummy input that’s fed to a file output; we’ve also got a wildcard stdout configuration to make it easy to observe what’s going on from the command line.
There are at this level, two telltale signs of self-monitoring at this level:
The includes declaration picks up otel.yaml, which includes additional inputs and outputs, as well as service configurations.
The service settings that switch on the HTTP server. It is controlled via environment variables, so you could switch this off easily. We have to implement these settings here, as within the full set of file inclusions, there can only be a single service block.
The service declaration also specifies where we want the log file that the Fluent Bit setup needs to go.
otel.yaml
We’ve separated the pipeline definitions for Fluent Bit observability to reuse the configuration across many deployments. As different deployments may need to talk to different instances of the observability backend (for example, when operating in a multi-cloud arrangement we have defined the environment variables that provide the credentials and target address).
We have defined additional environment variables at this level, so that anyone needing to understand master settings and the service values needs only look here. How this layer (or layers) is established is, to an extent, concealed. It also means we can use OpAMP to generate a configuration file, but we’ll come back to that.
The environment variables that we define to be used by the master.yaml switch the HTTP server on, and indicate which ports to use. Making this easy to check for the person or people defining the master.yaml makes it easier to avoid port collisions.
We also tell Fluent Bit where to write its logs through the service setting. To consolidate the configuration, that value references a different environment variable, so we can put all of our configurations together. Even if we didn’t have this level of redirection, it is worthwhile setting the value using an environment variable as the file location is needed both as our output for the service and the input for a plugin.. As you can see, we’ve just named the file. So the file created will be relative to wherever we run Fluent Bit from.
Let’s look at the inputs and outputs being used, and what they do:
Tail – this is the input that reads Fluent Bit’s logs, as we set Fluent Bit to log at debug level, we’ll see plenty of activity. Having Fluent Bit write to the file system, only for a thread in the same process to read it, is obviously inefficient. It can be optimised by using a RAMFS-like filesystem on Linux and a RAMDisk-like filesystem on Windows, so everything is in memory.
Fluentbit_metrics – this is the active collection of metrics, which we simply point to the server part of Fluent Bit. If you’re using Fluent Bit as a sidecar in a pod, this has to be done carefully because of how networking for containers within a pod is handled.
opentelemetry – This takes our different input signals we’ve been collecting and pushes them to the OTel-compliant service. If we had different backend products for different types of signals, then we’d need different or multiple plugins defined. Although OpAMP does infer an OTel-compliant backend.
That is the hard bit done. As a result of these inputs, we get the metrics and logs (and no traces are available). We now just need an OpenTelemetry output plugin to direct all the OTLP-represented signals. For simplicity, we’ve made use of a free account on Grafana Cloud.
otel-config.yaml
This configuration file is simple, which is key to making it easy for us to manage the connections setup using OpAMP. It simply defines the connection-based attributes needed, as shown:
While populating credentials in a file isn’t ideal, it makes it pretty straightforward for an OpAMP Client (observer or supervisor) to receive the credentials for the management side of the protocol, make them available to Fluent Bit quickly, and have Fluent Bit pick them up dynamically via hot-deploy functionality. This is precisely what we have implemented in our OpAMP. This approach works for both Fluent Bit and Fluentd configurations and we can even apply a similar approach for driving clients such as Elastic Beats.
This configuration file is simple enough that we can rewrite it whenever the configuration values are amended; there is no complexity in inserting such settings into the broader configuration. Furthermore, if Fluent Bit were running as an observed process rather than a supervised (i.e., child) process, setting environment variables could become problematic.
We can mitigate credential-related challenges in the file system by restricting filesystem permissions to the file being written, so only certain users and processes can access it. When working with containers, we can also keep this part of the file system within the image by using a transient storage layer.
Alternative strategy for securing credentials
An alternative approach would be for the client to receive the credentials and store them in an encrypted method, such as a credentials vault, and then the launcher for the process would read and decrypt the file as it launches Fluent Bit or another collector. The way we have implemented the client for our OpAMP certainly makes this possible, but it also complicates the process and suggests that the mechanics of credential management would be better handled by a distributed vault solution.
OpAMP’s assumption
The only niggle, is that when passing the connections, the protocol assumes that connection details are only needed for the collector. That’s fine if the collector includes the client side of the protocol. But as we know, the collector may be managed with a supervisor or observer process. We could use the connection for the collector and our supervisor, but that may not be what is wanted.
Visualising the configuration
We can visualise the relationships, like this:
Unpacking the server-side aspects
As you start to think about the server aspect of this, it gets potentially very complex. In simple scenarios, sending everything to a single Observability backend isn’t an issue.
But if you’re managing a multi-cloud, hybrid, or managed client setup, you’re likely to want separate backend instances for different collectors. In our setup, that means passing the different connection details to the client to populate otel-config.yaml. Understanding this deployment will require understanding the distribution. We will also need to manage potentially a concentrated catalogue of credentials, which will need to map to the collector nodes, and a means for the user to define the mapping. Creating a means to visualise the mapping, and ideally to allow the server to apply rules or infer assignments for more complex use cases such as multi-cloud, isn’t going to be simple.
Conclusion
We have a simple means to deploy configuration and observe our collector and the supervisor/observer process. Making server-side management in a large-scale environment easy to work with will require some consideration and potentially additional optional metadata. But the protocol supports all of this, but doesn’t mandate specifics. Which does mean that either the server has to be smart enough to know when what to do if it interacts with a client that has been built or configured to work with this server – which is an essential requirement, otherwise we lose the value of the
With the announcement of Fluent Bit v4 at Kubecon Europe, we thought it worthwhile to take a look at what it means, aside from celebrating 10 years of Fluent Bit.
Firstly, normally using Semantic Versioning would suggest likely breaking (or incompatible changes to use SemVer wording) changes. The good news is that, like all the previous version changes for Fluent Bit the numbering change only reflects the arrival of major new features.
This is good news for me as the author of Logs and Telemetry with Fluent Bit, as it means the book remains entirely relevant. The book obviously won’t address the latest features, but we’ll try to cover those here as supplemental content.
Let’s reflect upon the new features, their benefits, and their implications.
More flexible support for TLS (v1.3, choosing ciphers to enable)
New language for custom plugins in the form of Zig
Security Improvements
While security for many is not something that will get most developers excited about, there are things here that will make a CSO (Chief Security Officer) smile. Any developer who knows implementing security behaviors because it is a good thing, rather than because you have been told to do it, makes a CSO happy, puts them in a good place, to be given some more lianency when there is a need to do something that would get the CSO hot under the collar. Given this, we can now win those points with CSOs by using new Fluent Bit configurations that control TLS versions (1.1 – 1.3) and ciphers to support in use.
But even more fundamental than that are the improvements around basic credentials management. Historically, credentials and tokens had to be explicit in a configuration file or referenced back to an environment variable. Now, such values can come from a file, and as a result, there is no explicitness in the configuration. File security can manage access and visibility of such details. This will also make credentials rotation a lot easier to implement.
Processor Improvements
The processor improvements are probably the most exciting changes. Processors allow us to introduce additional activities within the pipeline as part of a process such as an input, rather than requiring additional buffer fetch and return which we see in standard plugin operations.
Of course, the downside is that if the processor introduces a lot of effort, we can create unexpected problems, such as back pressure, for example, as a result of a processor working hard on an input.
The other factor that extending processors bring is that they are not supported in classic format, meaning that to exploit such formats, you do need to define your configuration using YAML. The only thing I’m not a fan of, is that the configuration for these features does make me think I’m having to read algorithms expressed with Backus Naur form (BNF).
Trace Sampling
Firstly, the processors supporting OpenTelemetry Tracing can now sample. This is probably Fluent Bit’s only weakness in the Open Telemetry domain until now. Sampling is essential here as traces can become significant as you track application executions through many spans. When combined with each new transaction creating a new trace, traces can become voluminous. To control this explosion on telemetry data, we want to sample traces, collecting a percentage of typical traces (performance, latency, no errors, etc) and the outliers, where tracing will show us where a process is suffering, e.g., an end-to-end process is slowing because of a bottleneck. We can dictate how the sampling is applied based on values of existing attributes, the trace status, status codes, latencies, the number of spans, etc.
Conditionality in Processors
Conditionality makes it easier to respond to aspects of logs. For example, only when the logging payload has several attributes with specific values do we want to filter the event out for more attention. For example, an application reporting that it is starting up, and logs are classified as representing an error – then we may want to add a tag to the event so it can be easily filtered and routed to the escalation process.
Plugins with Zig
The enablement of Zig for plugin development (input, output and filters) is strictly an experimental feature. The contributors are confident they have covered all the typical use cases. But the innate flexibility supporting a language always represents potential edge cases never considered and may require some additional work to address.
Let’s be honest: Zig isn’t a well-known language. So, let’s start by looking briefly at it and why the community has adopted it for custom plugin development as an alternative to the existing options with Lua and WASM.
So Zig has a number of characteristics that align with the Fluent Bit ethos better than Lua and WASM, specifically:
It is a compiled rather than interpreted language, meaning that we reduce the runtime overheads of an interpreter or JIT compiler such as Lua and the proxy layer of WASM. This aligns to be very fast/minimal compute overhead to do its job, – ideal for IoT and minimising the cost of side-care container deployments.
The footprint for the Zig executable is very, very small—smaller than even a C-generated binary! As with the previous point, this lends itself to common Fluent Bit deployments.
The language definition is formally defined, compact, and freely available. This means you should be able to take a tool chain from anyone, and it is easy for specialist chip vendors to provide compilers.
Based on those who have tried, cross-compiling is far easier to deal with than working with GCC, MSVC, etc. Making it a lot easier to develop with the benefits we want from Go. Unlike Go – to connect to the C binary of Fluent Bit doesn’t require the use of a translation layer.
One of Zig’s characteristics that differs from C is its stronger typing and its approach of, rather than prescribing how edge cases are handled, e.g., null pointers, working to prevent you from entering those conditions.
Zig has been around for a few years (the first pre-release was in 2017, and the first non-pre-release was in August 2023). This is long enough for the supporting tooling to be pretty well fleshed out with package management, important building blocks such as the HTTP server, etc.
While asking a large enterprise with more conservative approaches to development (particularly when IT is seen as an overhead, and source of risk rather than a differentiator/revenue generator) to consider adopting Zig could be challenging compared to adopting, say Go. The different potential values here, make for some interesting potential.
Not Only, but Also
While we have made some significant advancements, each Fluent Bit release brings a variety of improvements in its plugins. For example, working with it with eBPF, HTTP output supports more compression techniques, such as Snappy and ZSTD, and Exit having a configurable delay.
The Plus version of library dependencies is being updated to exploit new capabilities or ensure Fluent Bit isn’t using libraries with vulnerabilities.
Testing OpenTelemetry configuration pipelines without resorting to instrumented applications, particularly for traces, can be a bit of a pain. Typically, you just want to validate you can get an exported/generated signal through your pipeline, which may not be the OpenTelemetry Collector (e.g., FluentBit or commercial solutions such as DataDog). This led to the creation of Tracegen, and then the larger Telementrygen.
You can use Tracegen or Telemetrygen by either downloading and running the Go app from GitHub or using the Docker file. But there are a couple of challenges:
On initial investigation, these utilities appear wrapped up in the larger opentelemetry-collector-contrib. While potentially useful, shaking out your OTel pipelining is somewhat overkill.
We can install the app locally with the following command, but then we need to set up Golang in the environment.
go install github.com/open-telemetry/opentelemetry-collector-contrib/cmd/telemetrygen@latest
Fortunately, there is a Docker image that just contains the tool, but to use it, we need to know what the parameters are to override the container defaults. The only irritant is that you either need to mess about with the container to get at the information (i.e., run the — help options) or install the utility (the parameters are not in the GitHub docs), so we’ve teased out all the options into the following table.
The following table’s Signal column All means it can be applied to Metrics, Traces, or Logs. Otherwise we’ve named the signal type that the parameter can be used with.
Signal
Parameter/Flag
Description
Trace
–batch
Whether to batch traces (default true)
All
–ca-cert string
Trusted Certificate Authority to verify server certificate
Traces
–child-spans int
Client certificate file
All
–client-key string
Client private key file
All
–duration duration
For how long to run the test
All
-h, –help {traces|metrics|logs}
help – with give you the basic help if no parameter is passed. Or the signal type help when used with the signal name e.g. telemetrygen traces --help
All
–interval duration
Reporting interval (default 1s)
Traces
–marshal
Whether to marshal trace context via HTTP headers
All
–mtls
Whether to require client authentication for mTLS
All
–otlp-attributes map[string]string
Custom resource attributes to use. The value is expected in the format key=”value”. Note you may need to escape the quotes when using the tool from a cli. Flag may be repeated to set multiple attributes (e.g --otlp-attributes key1=\"value1\" --otlp-attributes key2=\"value2\")
All
–otlp-endpoint string
Destination endpoint for exporting logs, metrics and traces
All
–otlp-header map[string]string
Custom header to be passed along with each OTLP request. The value is expected in the format key=”value”. Note you may need to escape the quotes when using the tool from a cli. Flag may be repeated to set multiple headers (e.g --otlp-header key1=\"value1\" --otlp-header key2=\"value2\")
All
–otlp-http
Whether to use HTTP exporter rather than a gRPC one
All
–otlp-http-url-path string
Which URL path to write to (default "/v1/traces")
All
–otlp-insecure
Whether to enable client transport security for the exporter’s grpc or http connection
All
–rate int
Approximately how many metrics per second each worker should generate. Zero means no throttling.
Traces
–service string
Service name to use (default "telemetrygen")
Traces
–size int
Desired minimum size in MB of string data for each trace generated. This can be used to test traces with large payloads, i.e. when testing the OTLP receiver endpoint max receive size.
Traces
–span-duration duration
The duration of each generated span. (default 123µs)
Traces
–status-code string
Status code to use for the spans, one of (Unset, Error, Ok) or the equivalent integer (0,1,2) (default “0”)
All
–telemetry-attributes map[string]string
Number of traces to generate in each worker (ignored if the duration is provided) (default 1)
Traces
–traces int
Number of traces to generate in each worker (ignored if duration is provided) (default 1)
All
–workers int
Number of workers (goroutines) to run (default of 1)
Metrics
–metric-type metricType
Number of metrics to generate in each worker (ignored if the duration is provided) (default 1)
Metrics
–metrics int
Number of logs to generate in each worker (ignored if the duration is provided) (default 1)
Logs
–body string
Body of the log (default “the message”)
Logs
–logs int
The severity number of the log ranges from 1 to 24 (inclusive) (default 9)
Logs
–severity-number int32
The severity number of the log ranges from 1 to 24 (inclusive) (default 9)
Logs
–severity-text string
Severity text of the log (default “Info”)
All the configuration parameters for Telemetrygen
It is worth noting that while Tracegen has similar configuration parameters, they aren’t exactly the same in the CLI, often one dash rather than two in the name for example.
The following is a simple Docker compose file that can help you use the container to conduct local testing of your collector. In this configuration, we’re sending a trace to the host machine with HTTPS disabled.
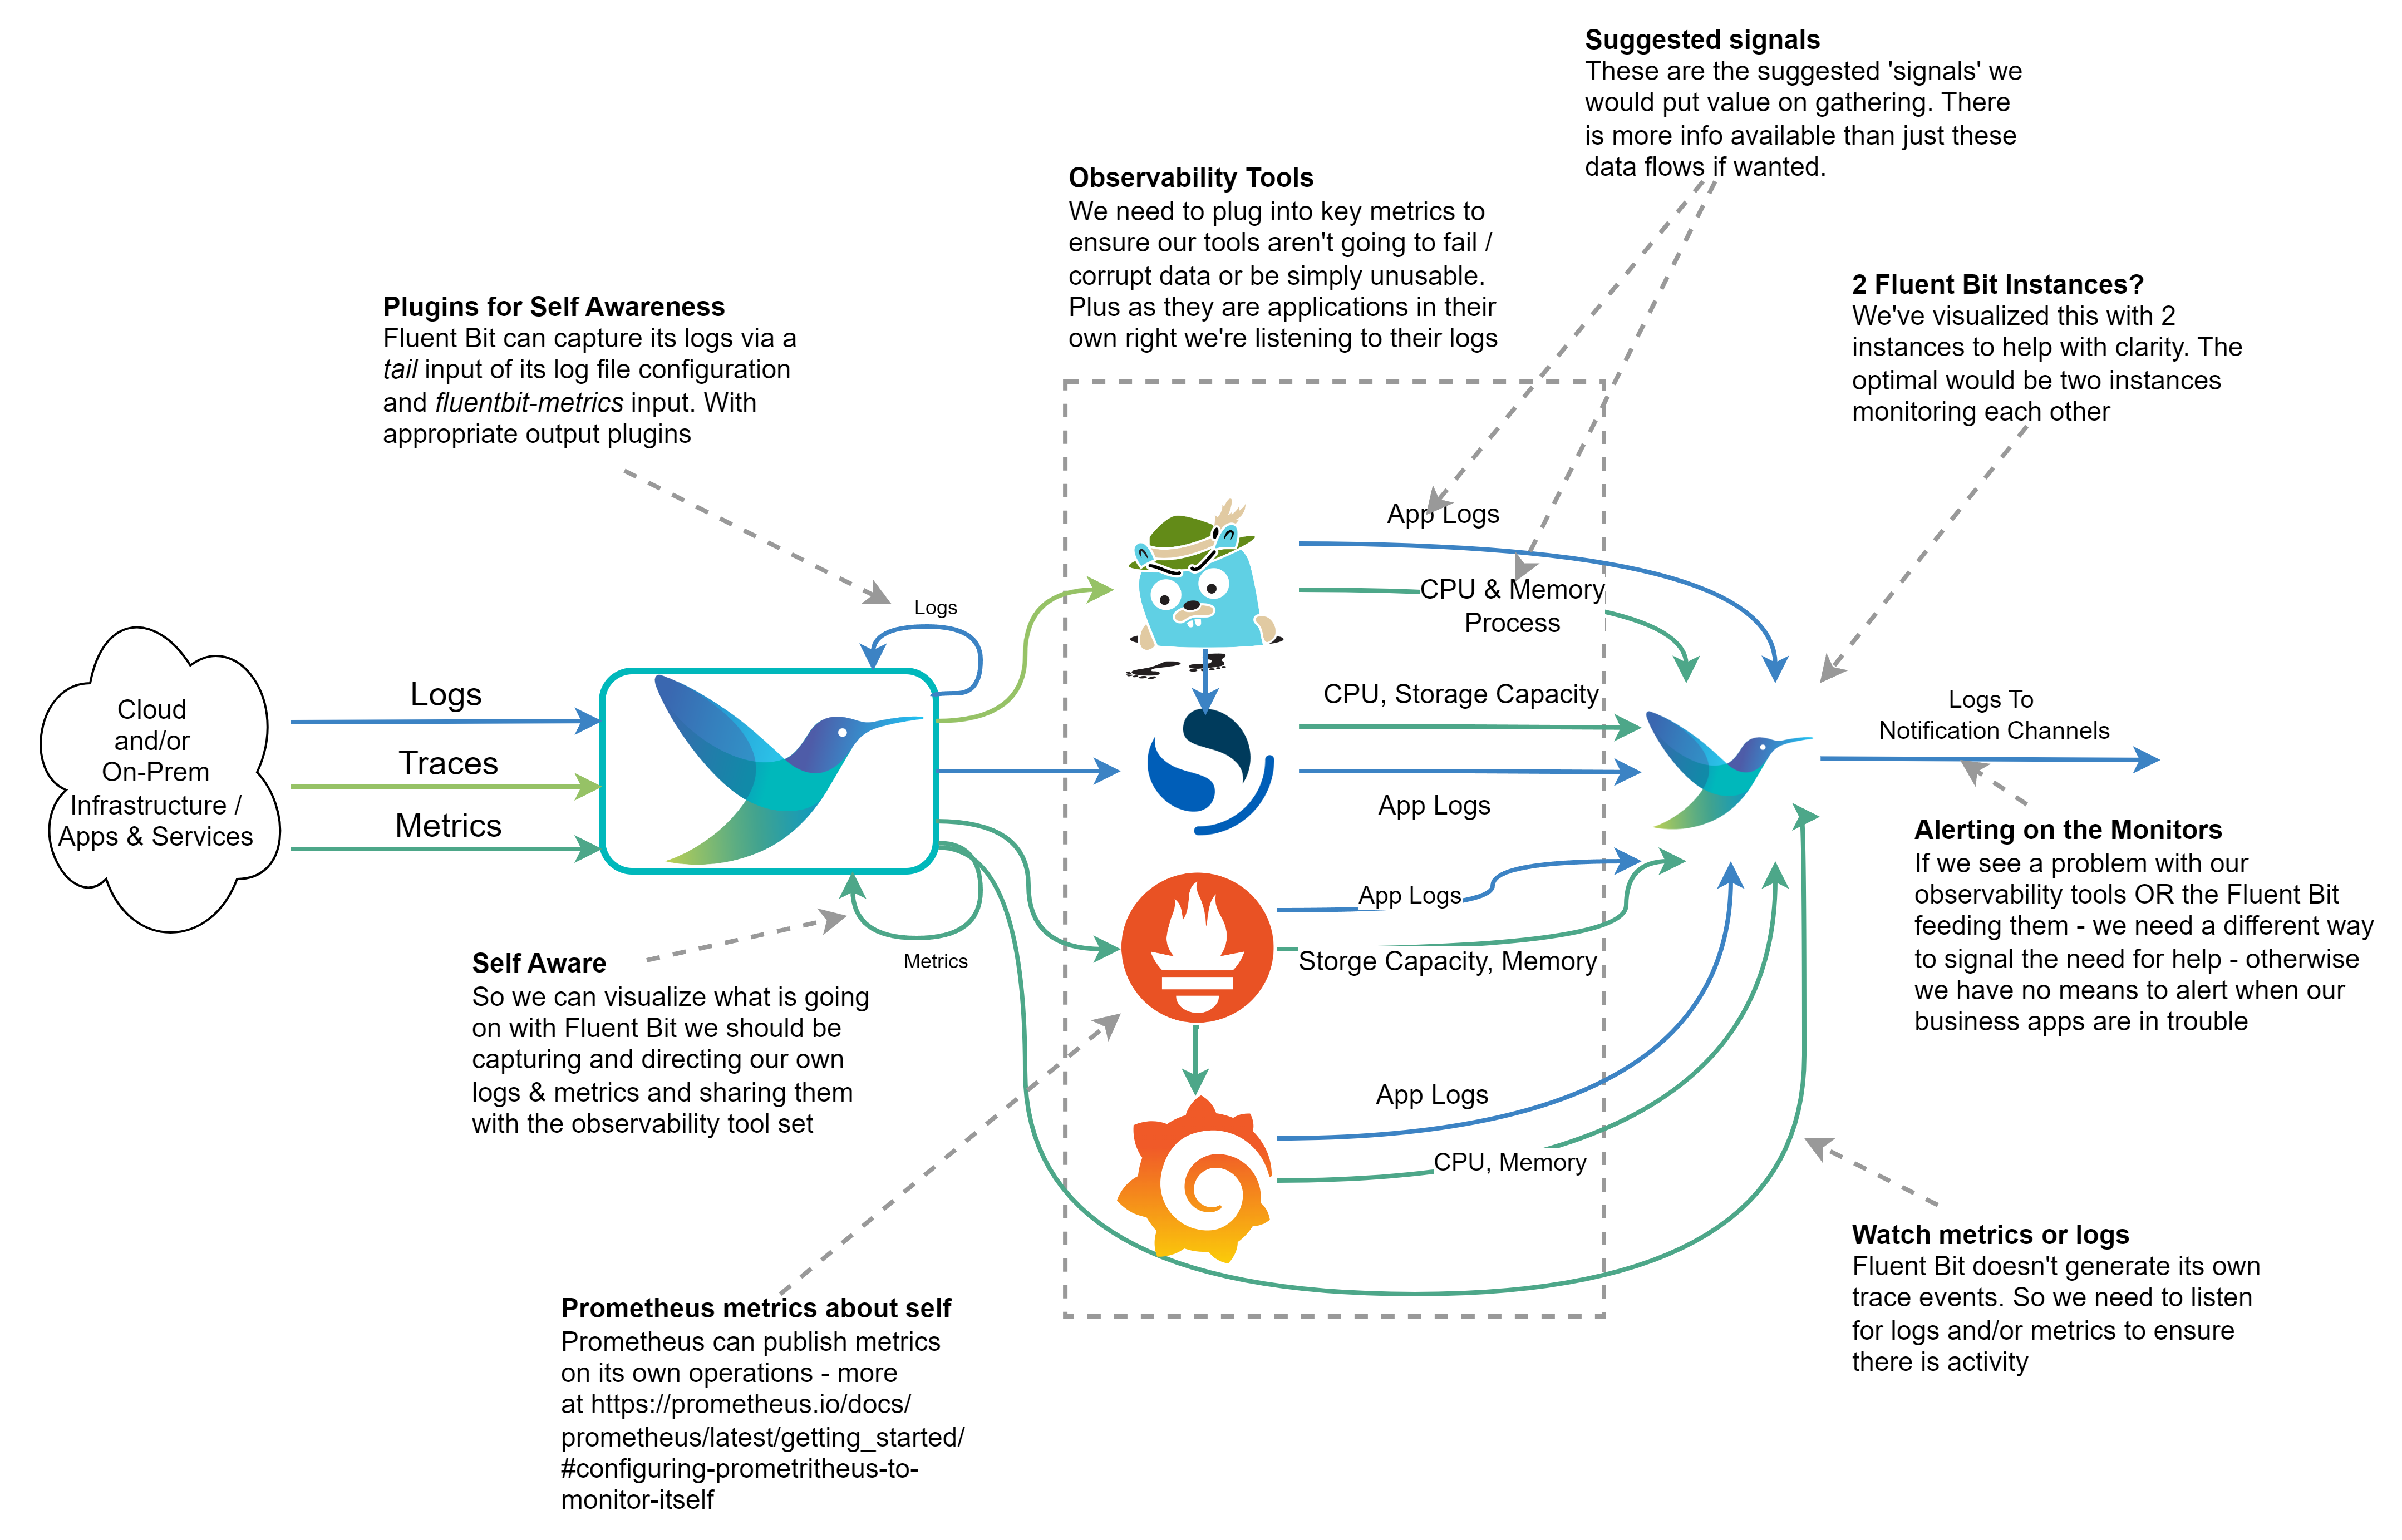
In the Fluent Bit book I touch upon the point that we should be observing the observer. After all, if we don’t monitor our observability stack, then we’ll be operating blind and may never know until things go catastrophically wrong, and we’re getting complaints that production business solutions are down. One of the peer review comments was it would be really good to have a visual representation in the book. While I’d love to incorporate such diagrams, for them to be readable, they do use up a lot of space on the printed page, and very long chapters can also put some readers off. So, given the point wasn’t a key theme, we simply couldn’t incorporate the diagram.
But the suggestion is a good one. So we’ve created the visual representation here.
The diagram shows how we can monitor our observation tech stack so we don’t become ‘blind’ without knowing about it. The Outflow from the right of the diagram would send a signal to a notification service, which could be as simple as email or as user-friendly as Slack. We’ve indicated which kinds of metrics, logs, and traces could offer the most value from our observation tech stack.
If we’re running everything within a Kubernetes cluster, it would be easy to say we don’t need such a sophisticated setup as we can use Kubernetes liveness probes if the containers are well configured. While it is true if one of our services starts to fail, a liveness check should pick it up and recycle the container. But such probes only worry about the HTTP response code, not the cause. If we don’t monitor and capture more information we’ll never understand the problem. At worst we could end up seeing Kubernetes starting and then killing our containers in a vicious cycle and struggling to resolve the cause. So collecting the logs and metrics remains just as important.
How to Publish Fluent Bit Metrics and Logs
To publish Fluent Bit’s metrics to Prometheus, we need to configure the fluentbit-metrics input plugin (it does sound odd as an input, but there are reasons that become clearer in the book). We then route the output that supports using Fluent Bit as a Prometheus node exporter or makes use of the remote write API.
The log output for Fluent Bit can be configured via the command line or in the SERVICE blog (using the attributes log_file and log_level in the configuration file. Today this is setting the log threshold and identifying the log file. We can then, of course, configure a tail input plugin against the file if we want to send the logs to OpenSearch. We can also set plugin-specific logging thresholds as overrides to the Fluent Bit wide setting in the SERVICE block of configuration.
Configuring the other monitoring tools
Grafana‘s configuration will allow it to publish Prometheus scrapable metrics and Traces that are OTLP compliant can be found documented here.
Prometheus provides metrics on itself (details here) and logging controls as part of its command line and generates logfmt or JSON logs, details here.
OpenSearch‘s logs can be accessed as documented here. The Logs are created with Log4j2, which means out of the box, it will be easy to parse them. Configuring the output of slow query reports does need to be switched on. OpenSearch also illustrates a pre OpenTelemetry/OpenMetrics approach to sharing internal metrics by writing them as logs. However, there are ways to convert such log events to OTLP Metrics with Fluent Bit.
Jaeger provides metrics endpoints that are Prometheus-compatible, along with JSON-based logs, and are documented here. There is some support for tracing.
Fluentd is both an open source solution for making log management so much easier to work with, particularly for distributed / multi component solutions. But not only that it is supported by many log analytics tools, and central to several cloud vendors log management services.
The goal of the book is to explain how Fluentd can help us and to use the tool. We can’t cover every possible plugin, so we walk through the use of enough plugins and the way features interact you can extrapolate to other plugins.



You must be logged in to post a comment.